
DaoyuanLi2816 / can-i-finetune-this
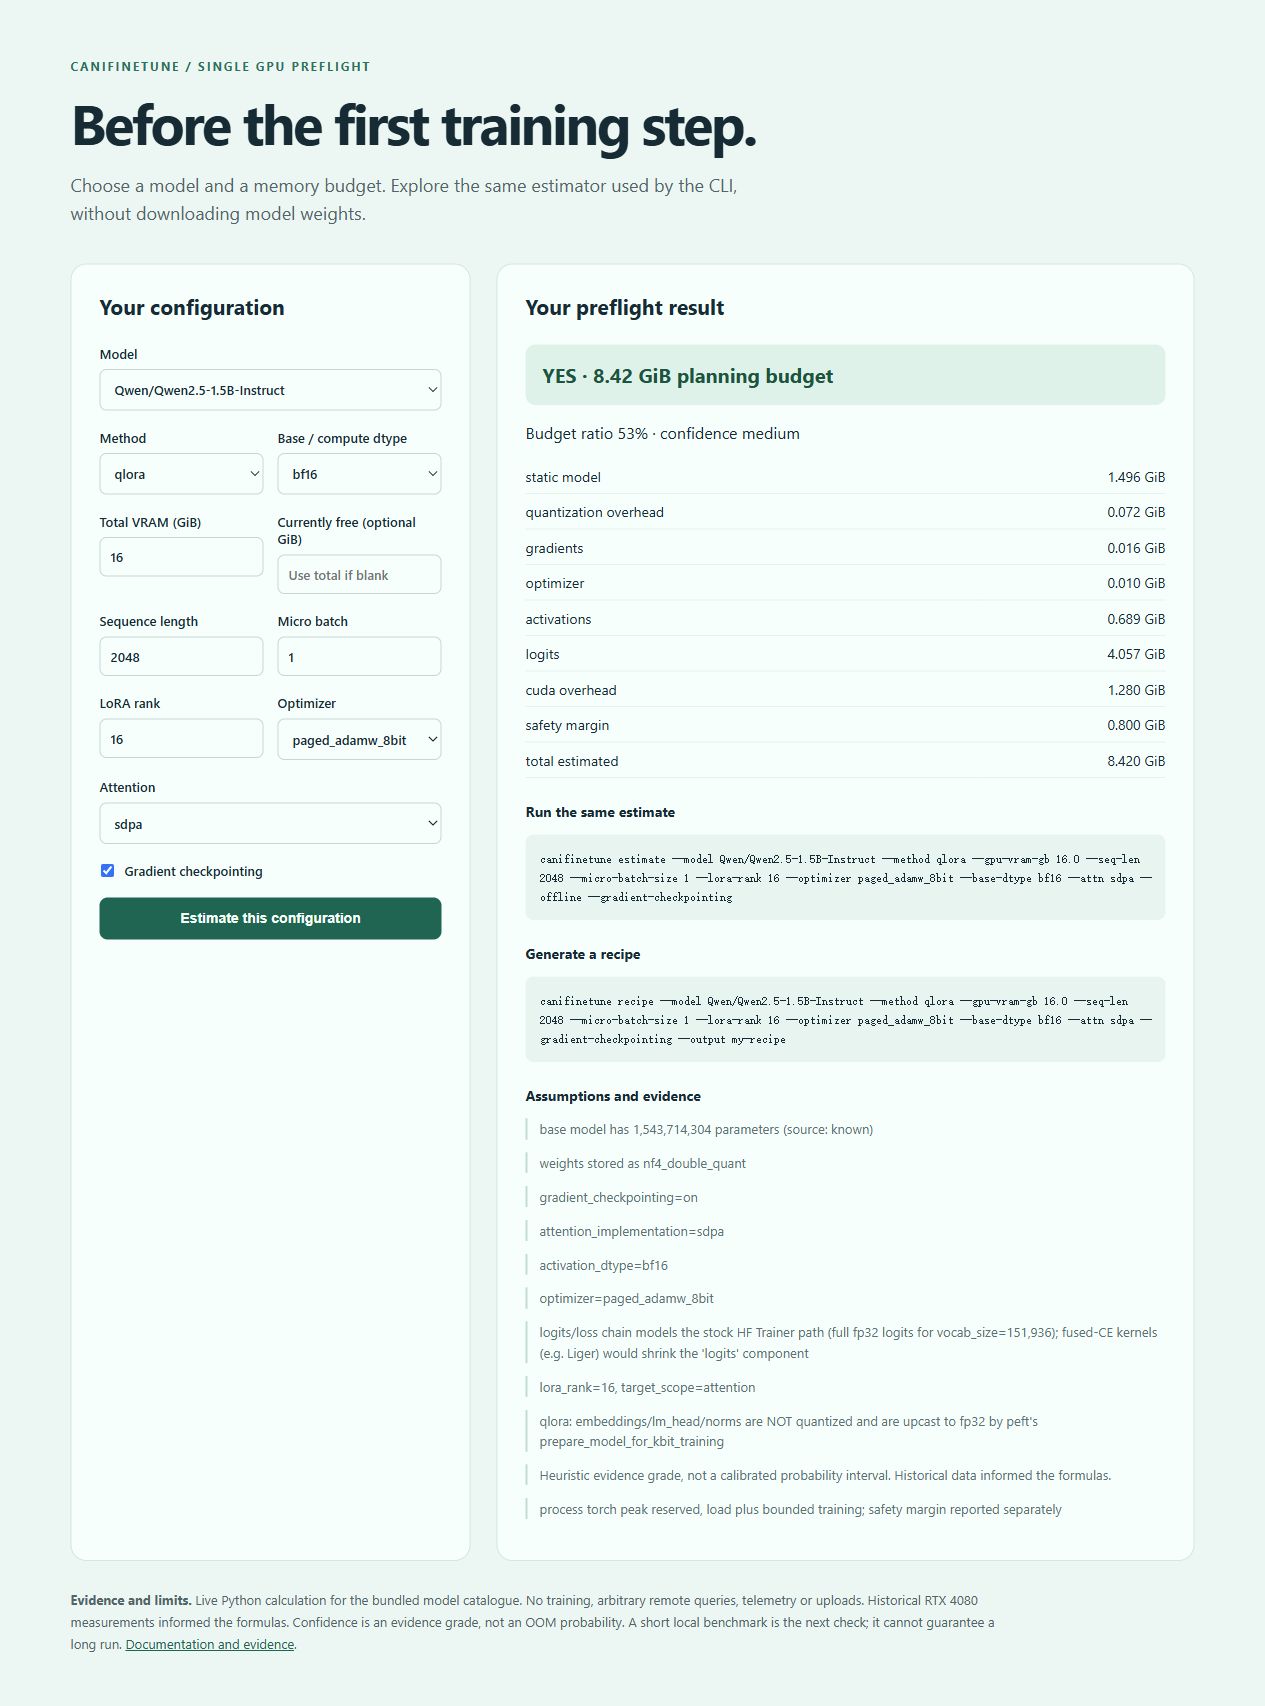
Single-GPU LLM fine-tuning preflight: memory estimates, runnable LoRA/QLoRA recipes, and local measurements.
Why this job: says: fine tuning, finetune, lora; topics: fine-tuning, lora, peft
What it does
You have one consumer NVIDIA GPU and an open-weight model in mind. How much memory will training need? Which sequence length, batch size and LoRA rank should you start with? What should you change when the budget is tight?
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 36 days ago
- Stars
- 795
- On GitHub
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v0.4.1
- Released 36 days ago
- Built with
- Python
- 90% of the code
Is it looked after?
- Contributors
- 1
- Last 90 days
- Issues
- None
- No issues filed
- Pull requests
- 14 merged
- 1 waiting
- Releases
- 6
- 6 in the last year
- Contributing guide (opens in new tab)
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| hiyouga / LlamaFactory | 75,952 | today | Apache-2.0 | No downloads |
| huggingface / peft | 21,880 | today | Apache-2.0 | No downloads |
| MakazhanAlpamys / Soup | 10,336 | yesterday | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Python 90%
- HTML 7%
- Jinja 2%
- Shell 1%
Topics
- bitsandbytes
- fine-tuning
- gpu
- hugging-face
- llm
- lora
- memory-estimation
- peft
- pytorch
- qlora
- transformers
- vram
Project record
- JobFine-tuning
- StatusListed
- Commits64
- Forks107
- Watching88
- Stars in 28 days+2
- CreatedMay 16, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026