
gpustack / gpustack
A GPU cluster manager for high-performance AI model serving (vLLM, SGLang) and on-demand SSH-accessible GPU instances.
Why this job: topics: llm-inference, vllm, inference, llm-serving, llama, model serving
What it does
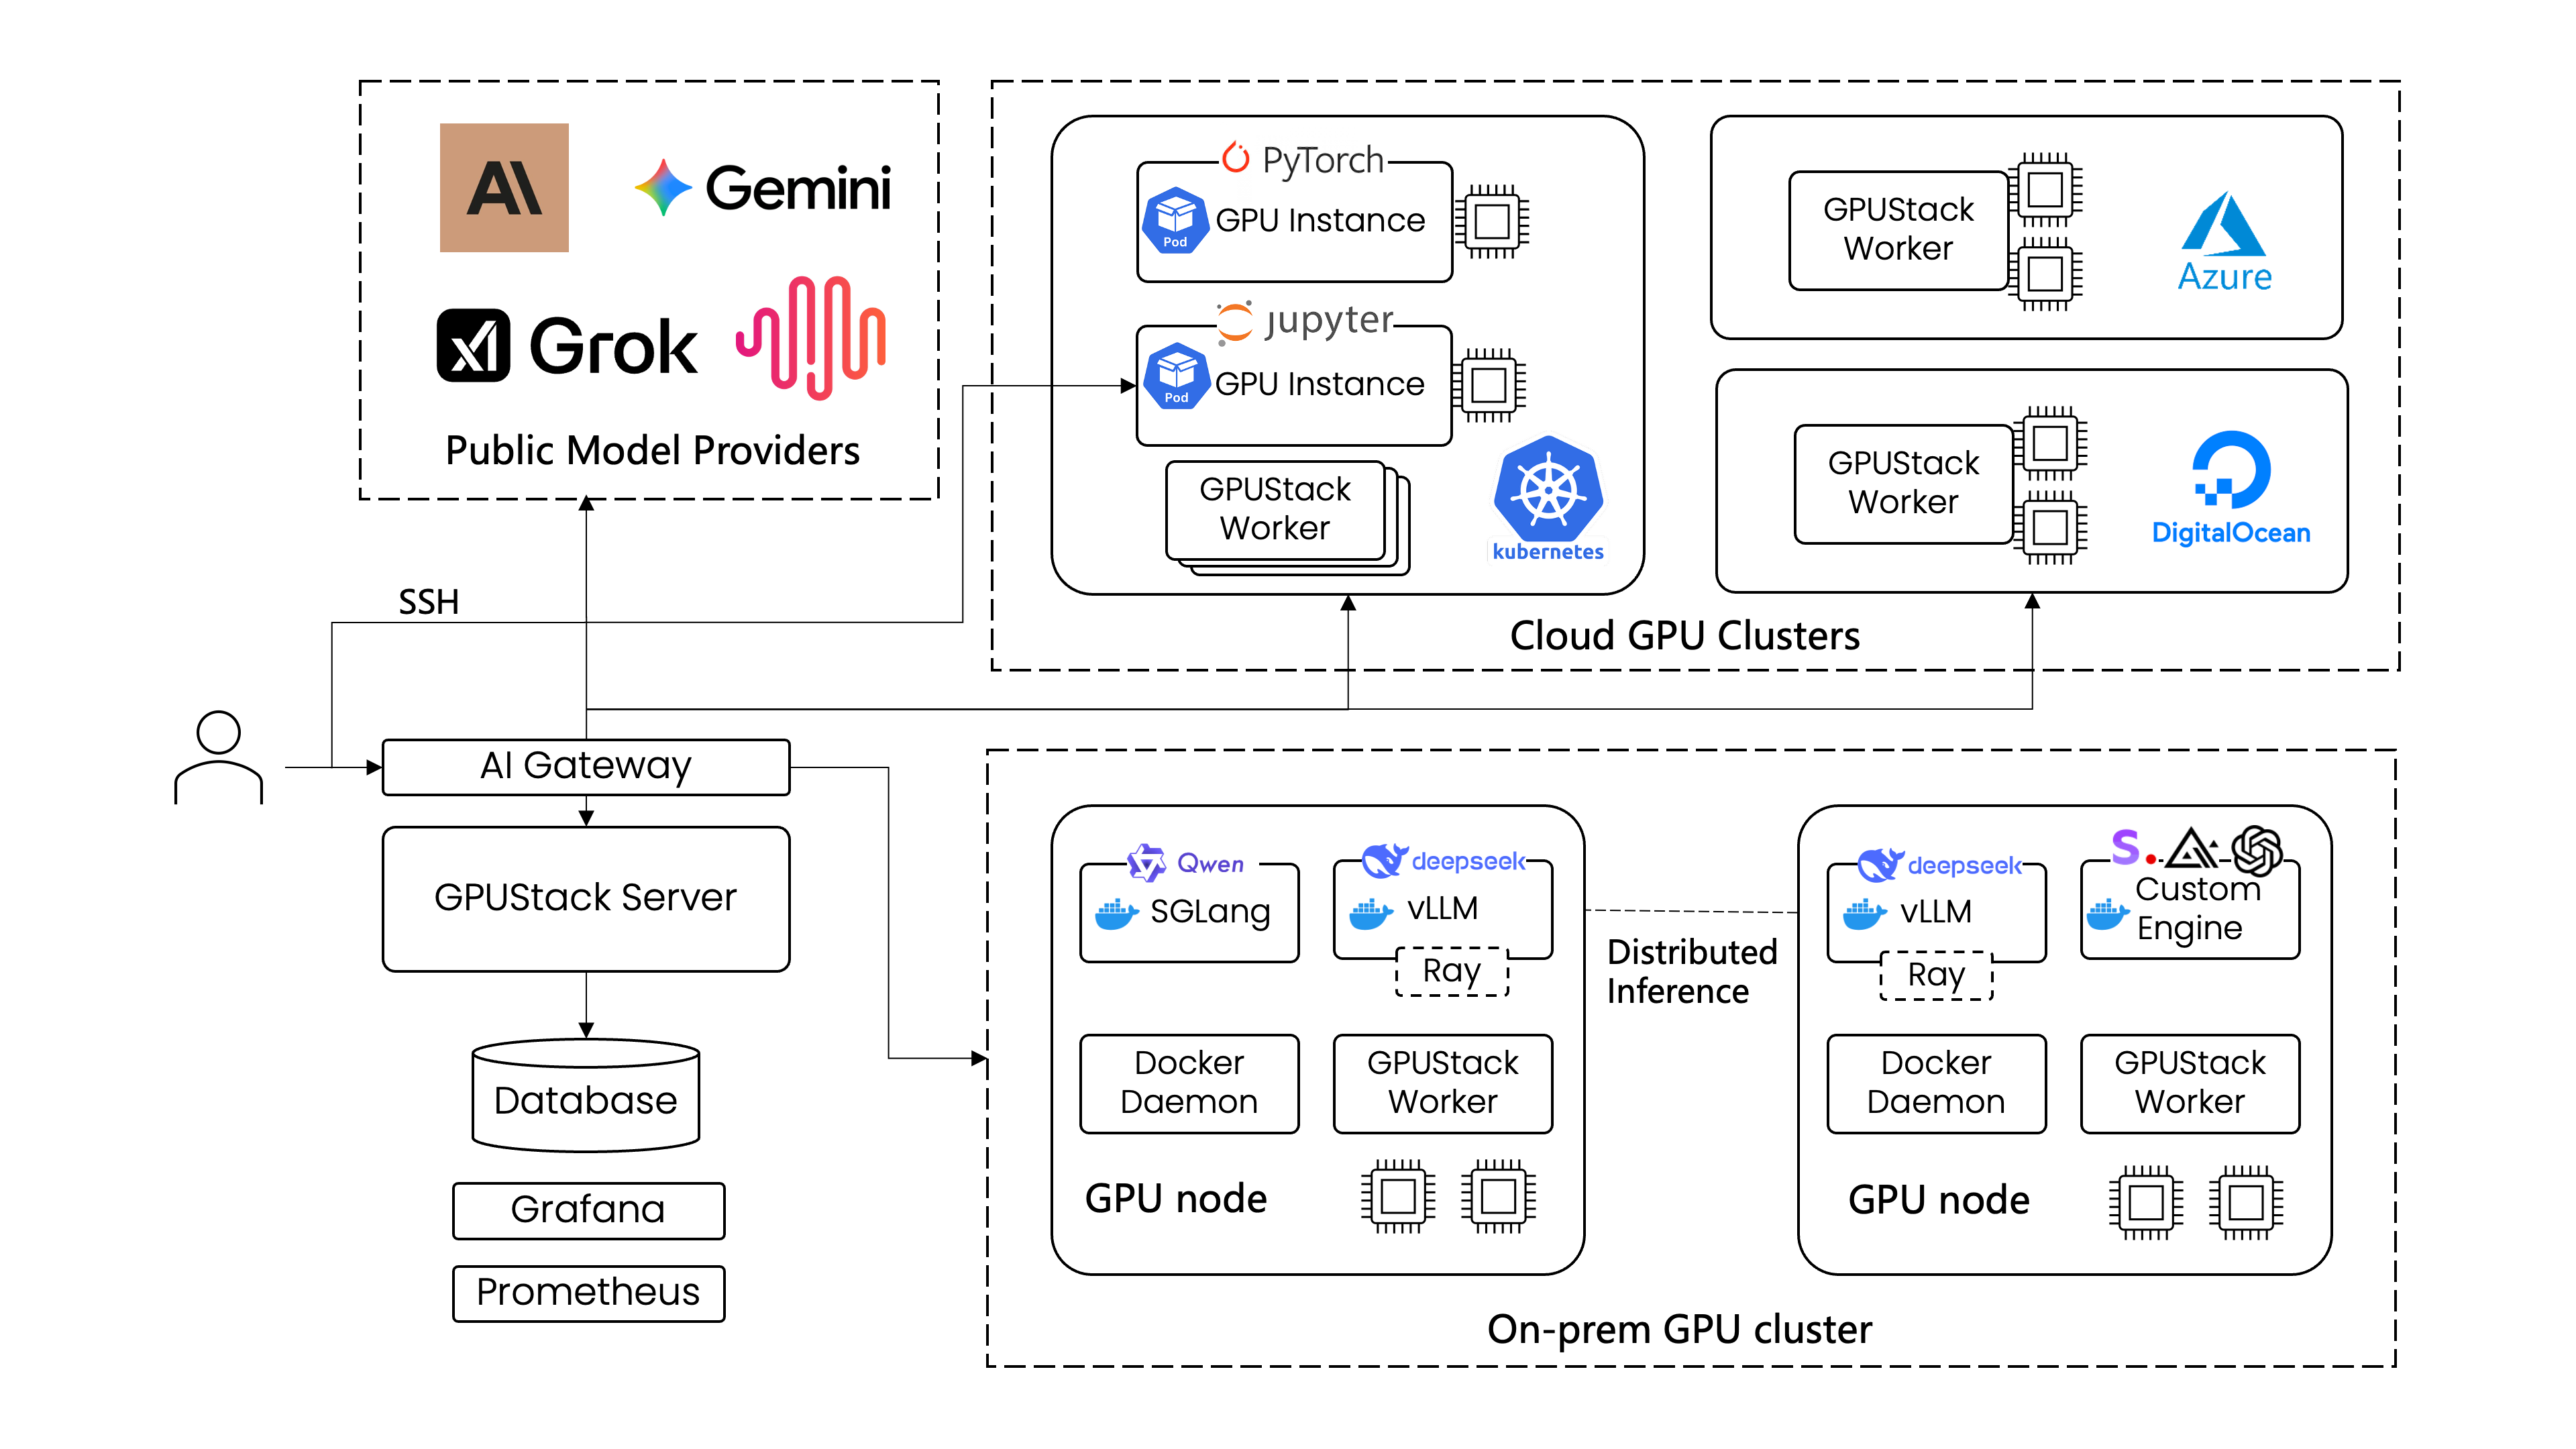
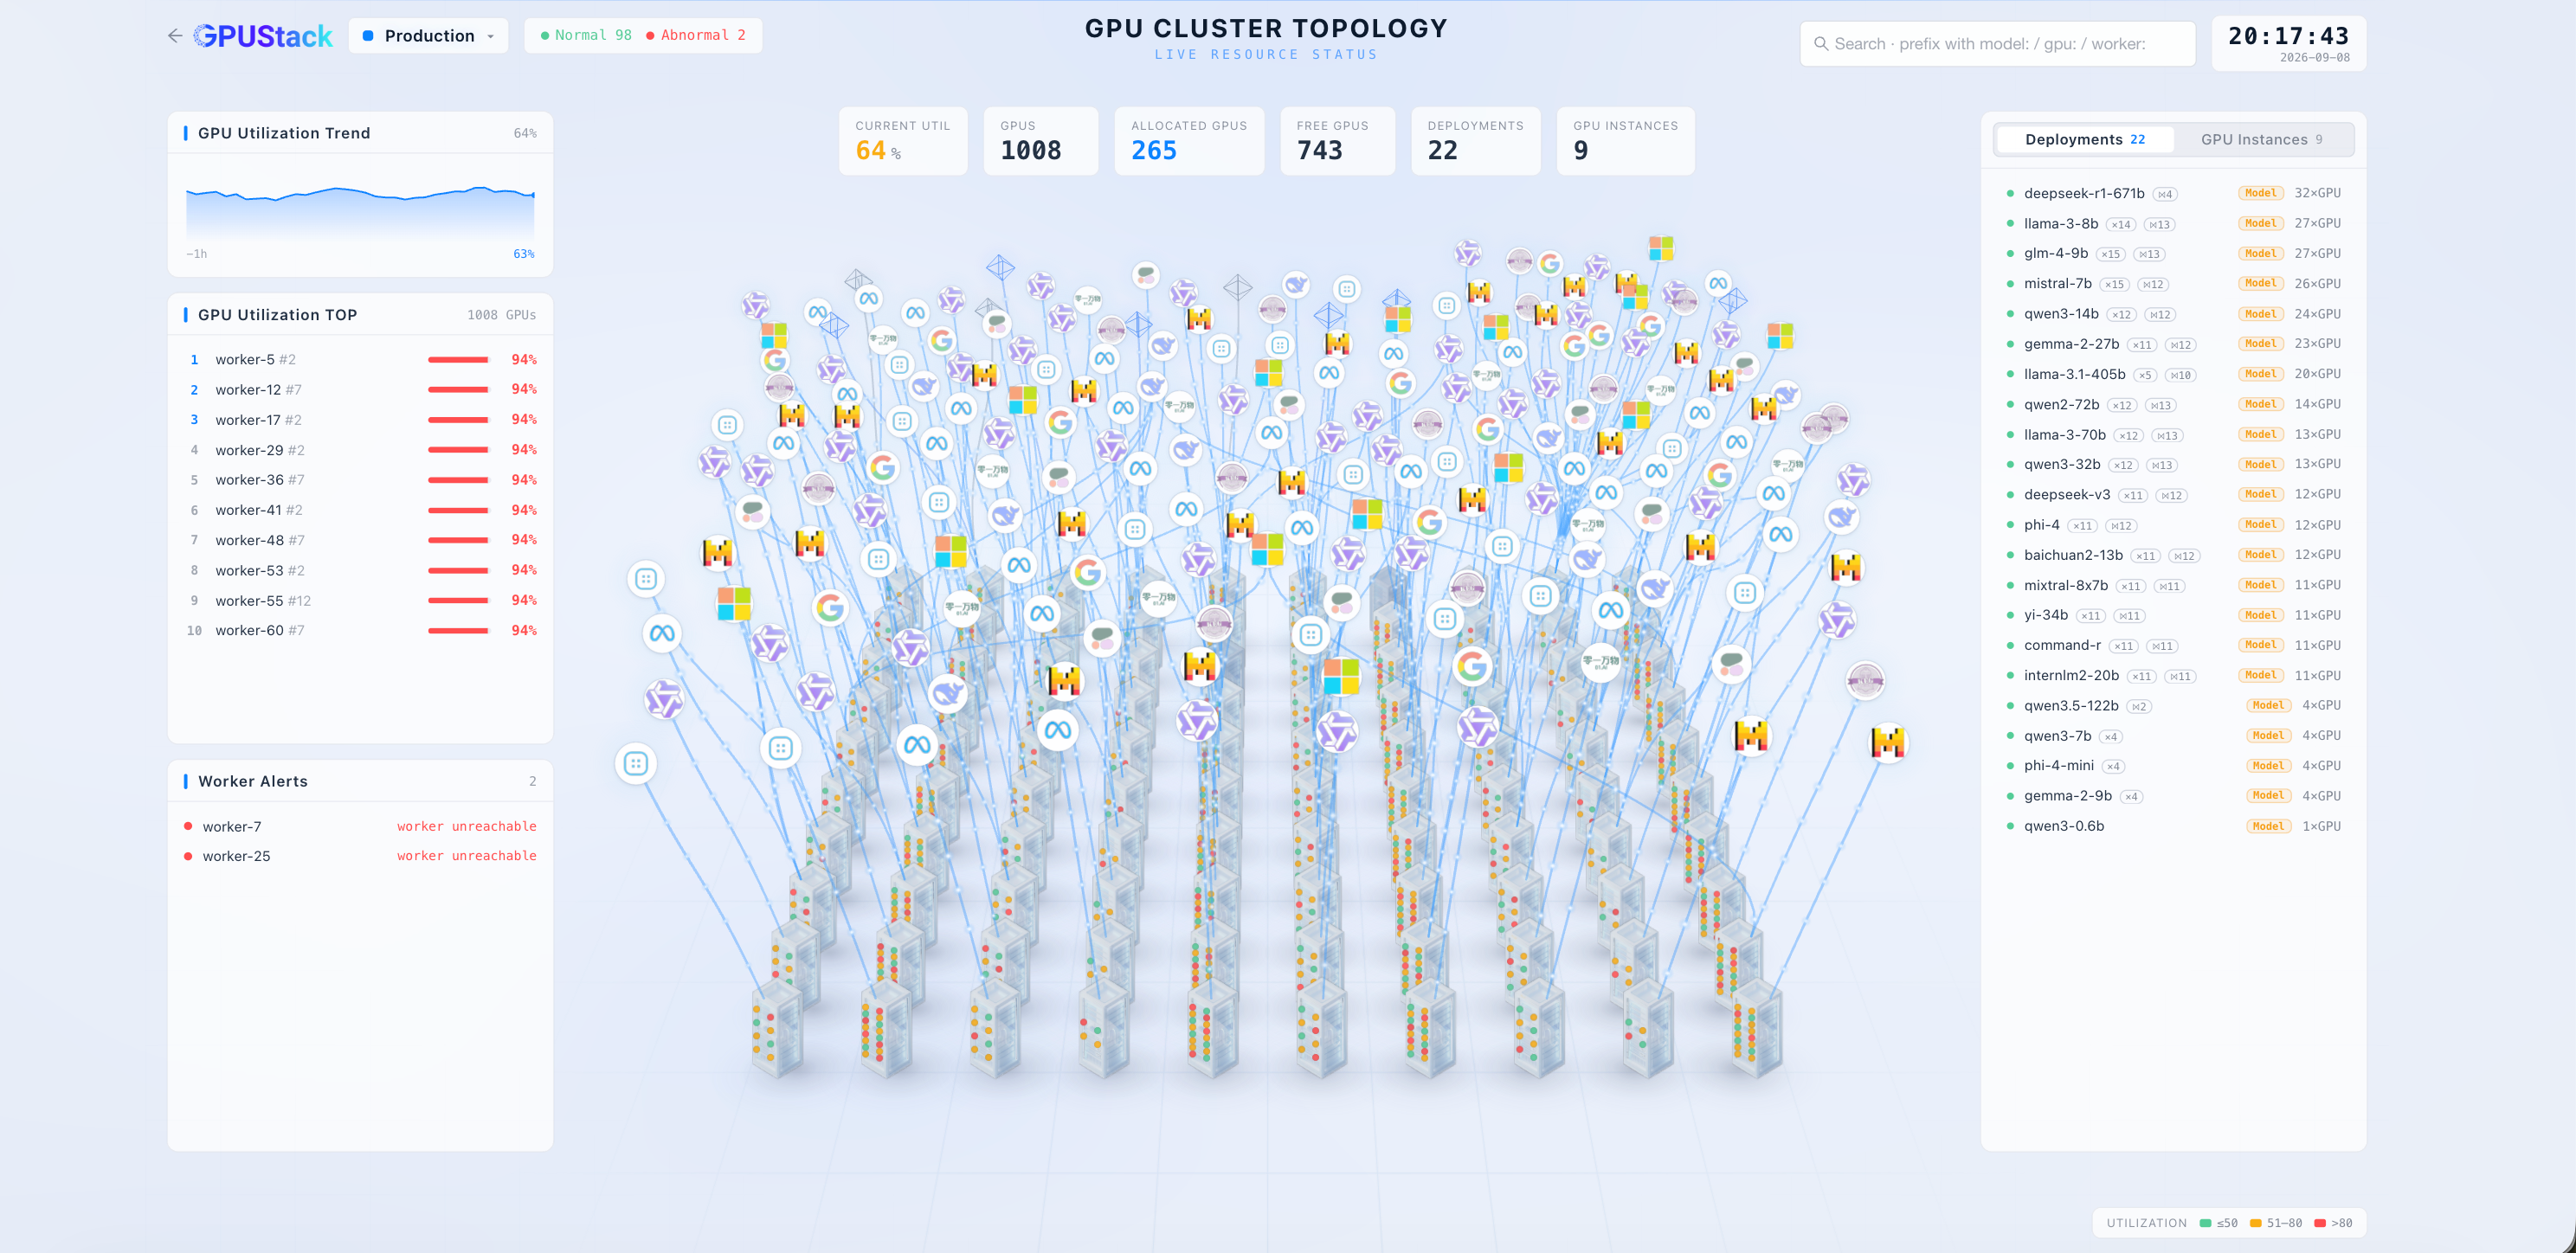
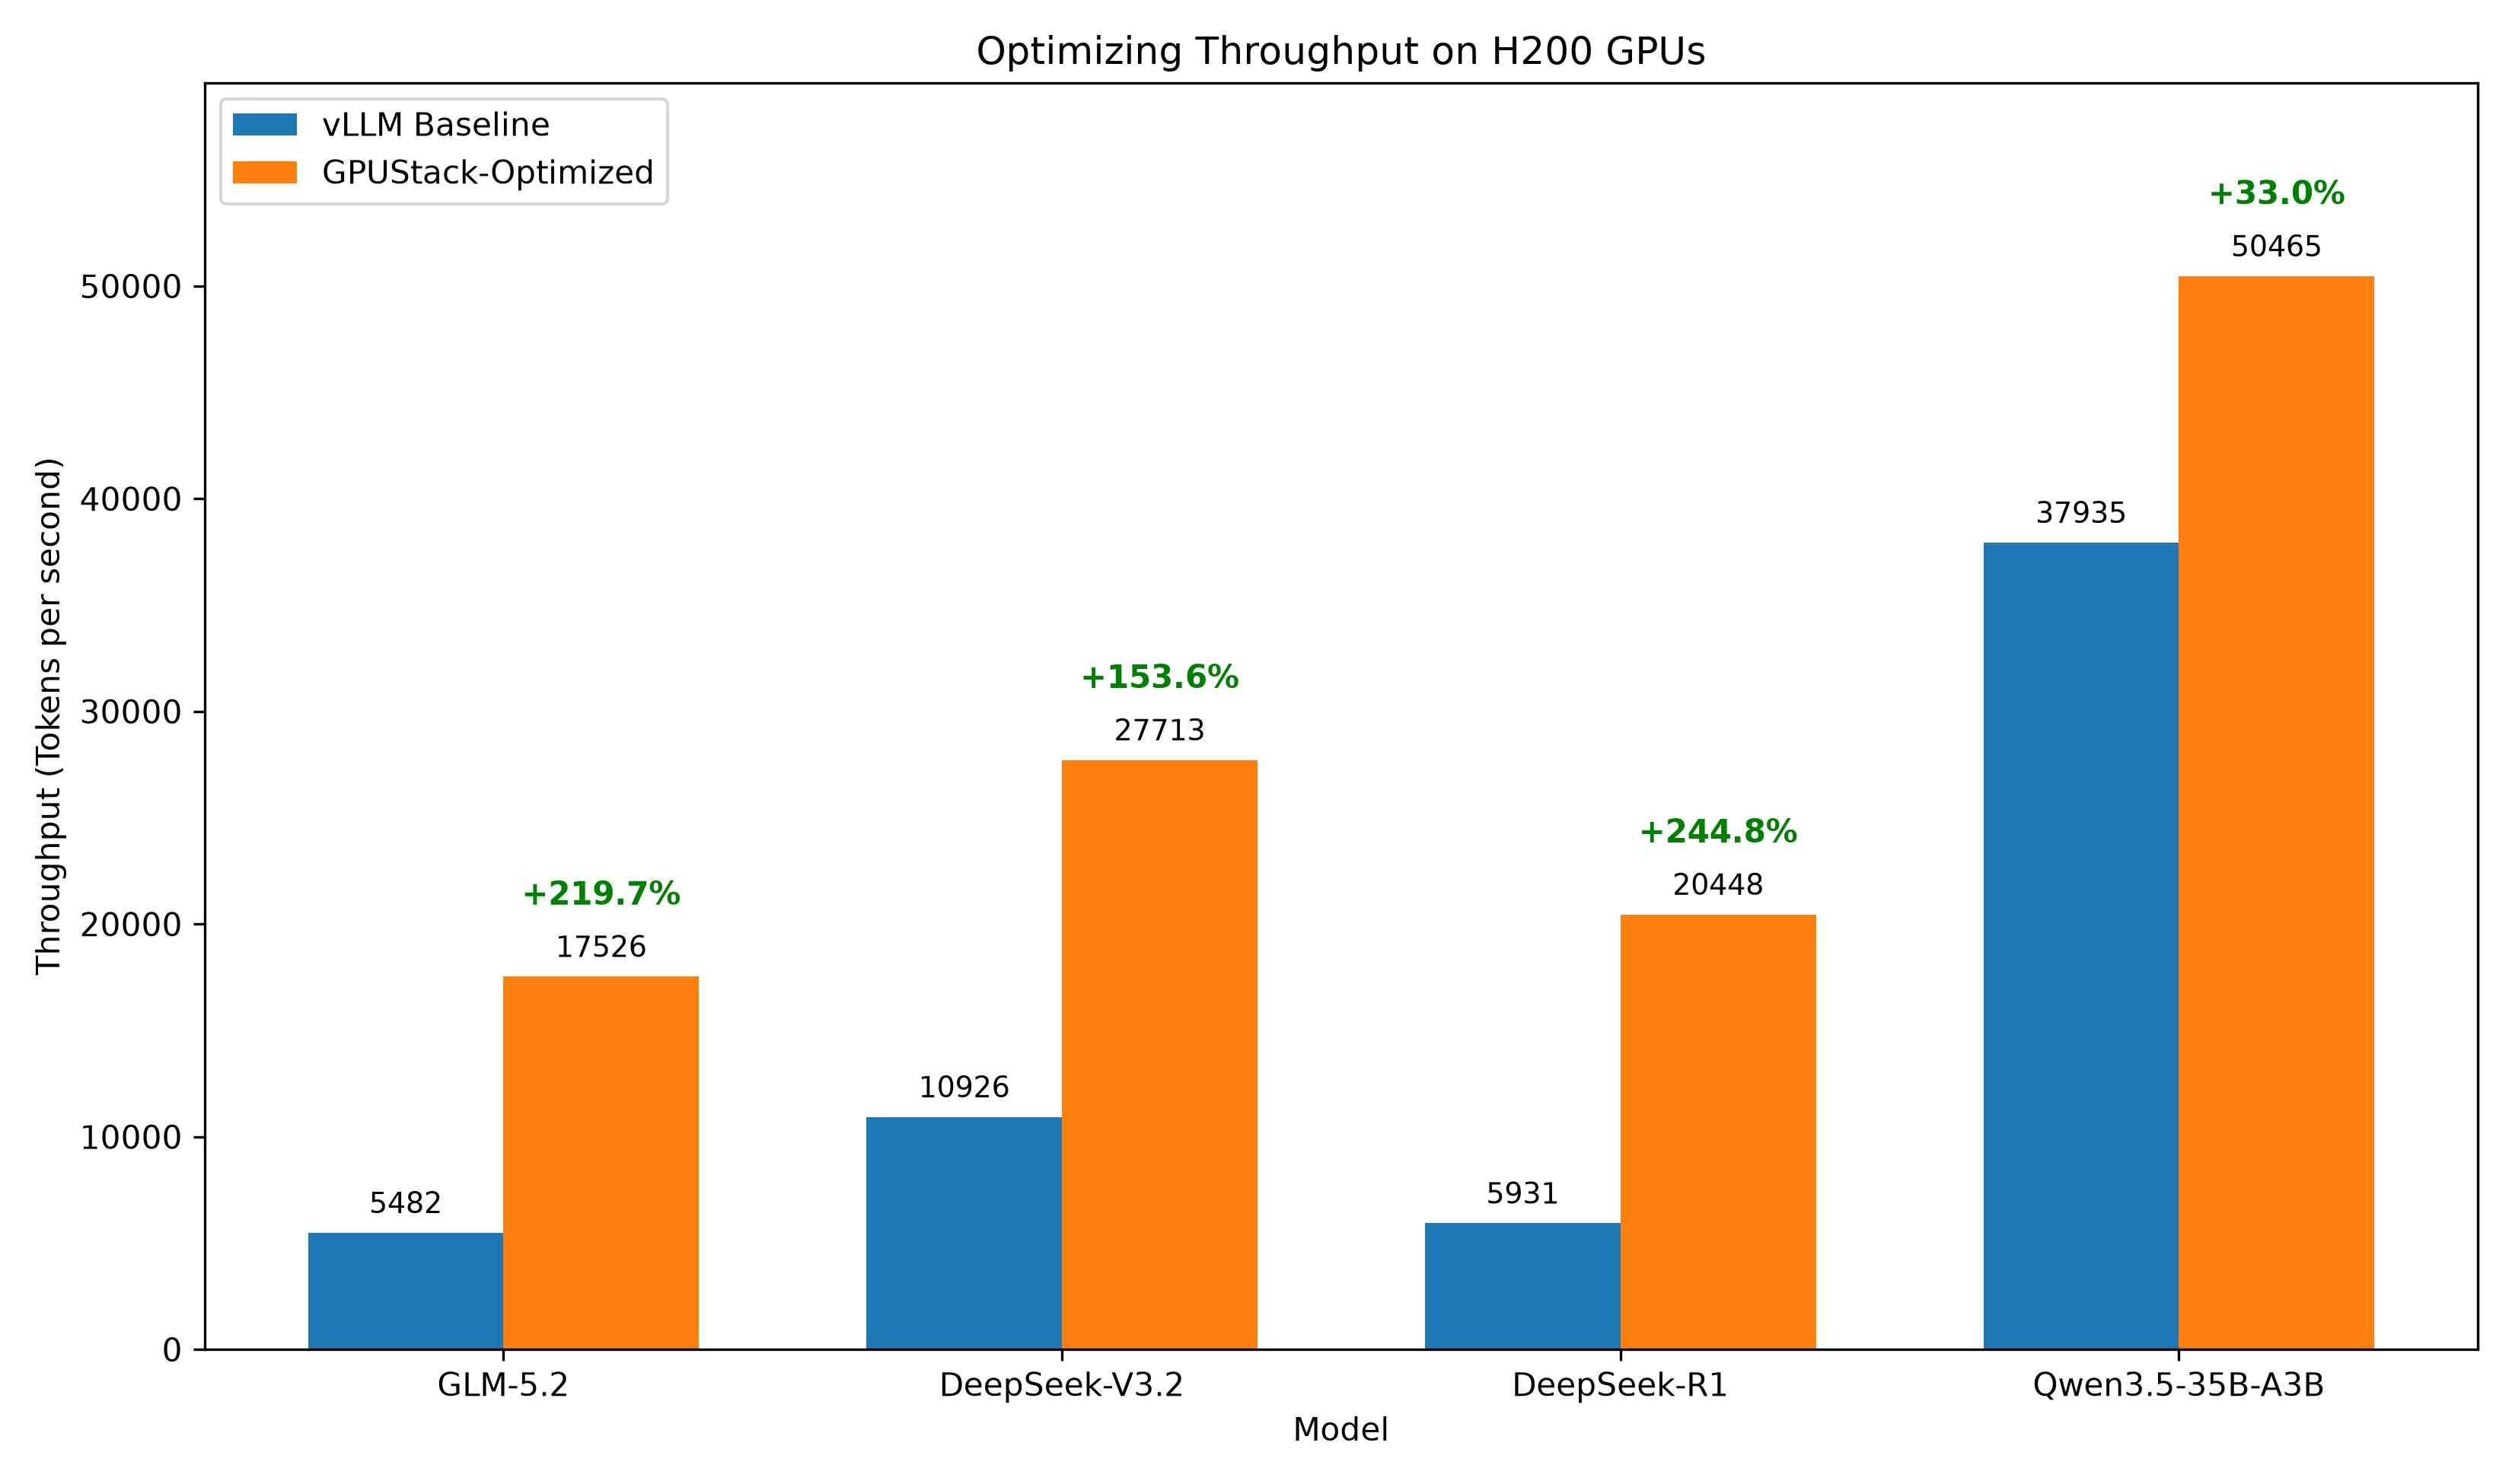
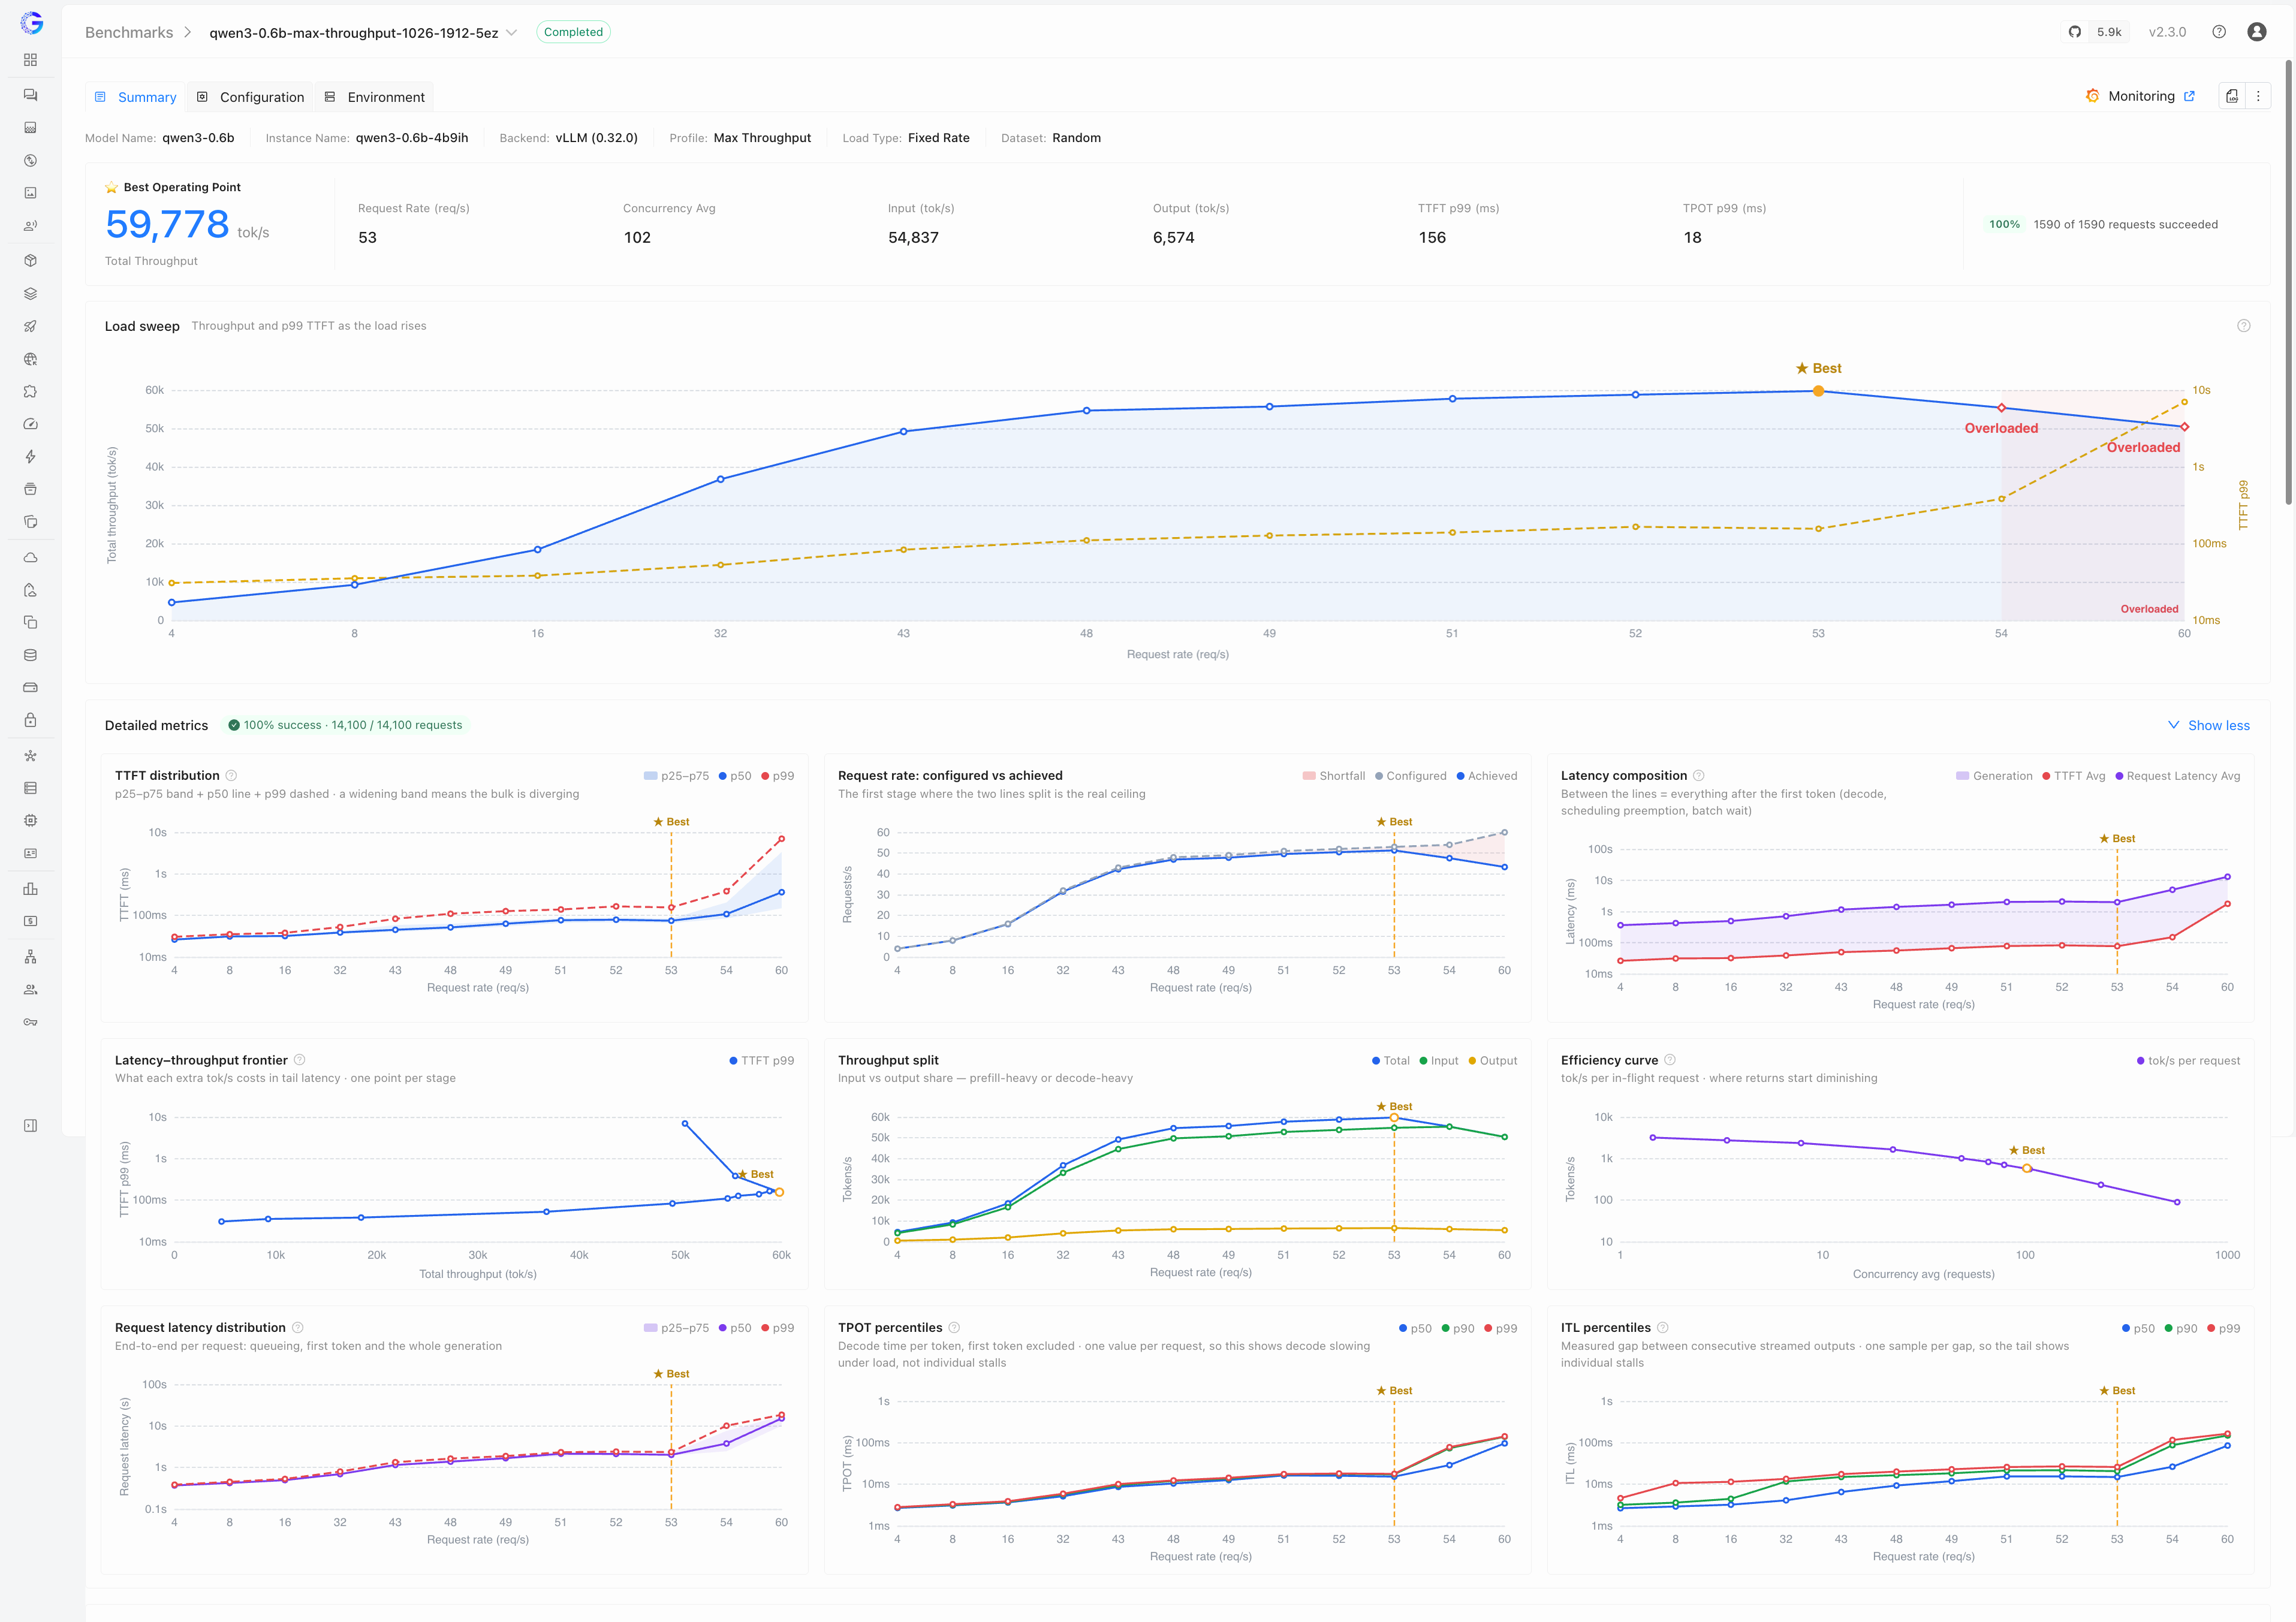
GPUStack is an open-source GPU cluster manager for AI model serving and GPU instance provisioning. It configures and orchestrates inference engines — vLLM, SGLang, TensorRT-LLM, or your own — and lets you launch SSH-accessible GPU instances on demand. Its core features include:
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit today
- Stars
- 6,005
- +46 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v2.3.0
- Released 18 days ago
- Built with
- Python
- 99% of the code
Is it looked after?
- Contributors
- 13
- Last 90 days
- Issues
- 83% closed
- 665 still open
- Pull requests
- 2,629 merged
- 86 waiting
- Releases
- 72
- 30+ in the last year
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| SemiAnalysisAI / InferenceX | 2,016 | today | Apache-2.0 | No downloads |
| vllm-project / vllm | 96,634 | today | Apache-2.0 | Mac, Linux |
| LMCache / LMCache | 12,321 | today | Apache-2.0 | Linux |
More: languages, topics and project record
Languages
- Python 99%
- Shell <1%
- Jinja <1%
- Dockerfile <1%
Topics
- ascend
- cuda
- deepseek
- distributed-inference
- genai
- inference
- llama
- llm
- maas
- openai
- qwen
- rocm
Project record
- JobLocal LLMs
- StatusListed
- Commits3,902
- Forks729
- Watching44
- Stars in 28 days+188
- CreatedMay 11, 2024
- First seen by usNov 7, 2026
- CheckedNov 10, 2026