
maximpri / mlxtop
A top for local LLMs: memory, paging, GPU and tokens/s for oMLX, Ollama, llama.cpp, vLLM and more
Why this job: topics: apple-silicon, llama-cpp, ollama, local-llm, vllm, mlx, local llms, llama.cpp
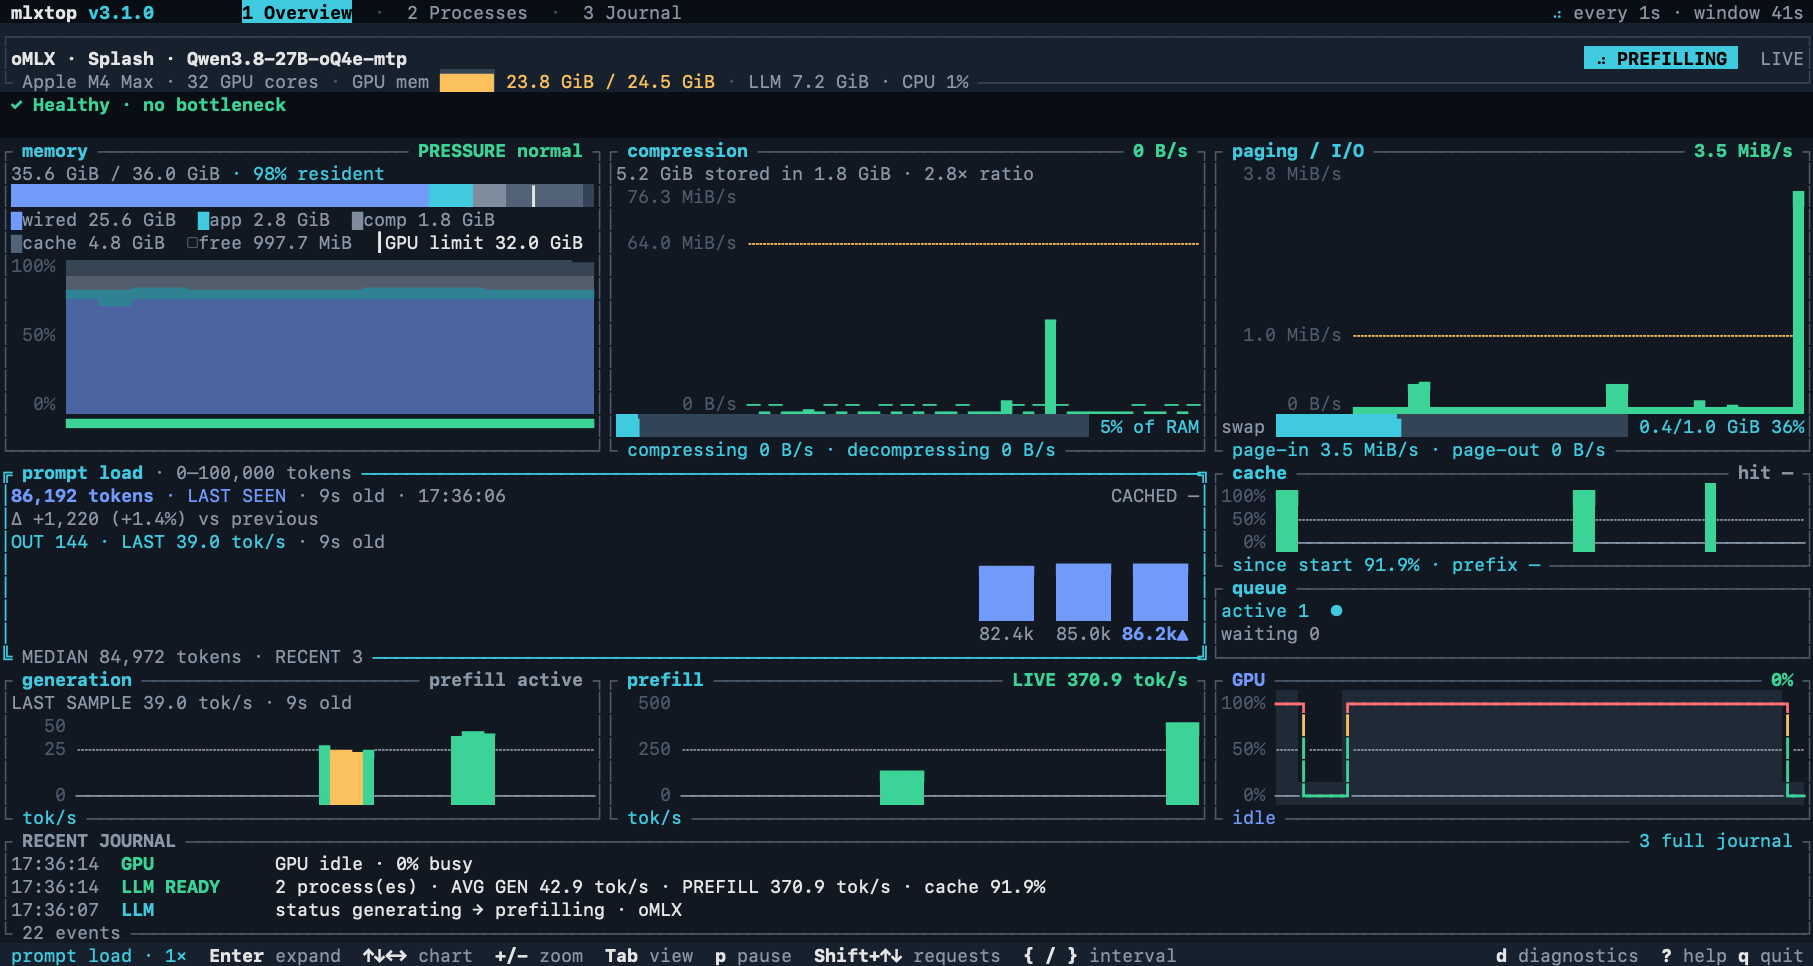
What it does
When a local model slows down, the cause is usually the machine: memory pressure, swapping, a full GPU or a throttled card. mlxtop shows those readings next to your runtime's own numbers, such as tokens per second, prefill progress, queued requests and cache reuse, so you can see which one changed when the model slowed.
Get started
brew install maximpri/tap/mlxtop - Maintenance
- Active
- Last commit 6 days ago
- Stars
- 148
- +5 this week
- Licence
- MIT
- Allows business use
- Downloads for
- 3 systems
- Mac, Windows, Linux
- Latest version
- v3.2.1
- Released 6 days ago
- Built with
- Rust
- 94% of the code
Is it looked after?
- Contributors
- 4
- Last 90 days
- Issues
- 100% closed
- 0 still open
- Pull requests
- 57 merged
- 0 waiting
- Releases
- 13
- 13 in the last year
- Contributing guide (opens in new tab)
- Security policy (opens in new tab)
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| vllm-project / vllm-metal | 1,974 | today | Apache-2.0 | Mac |
| llmmanorg / llmman | 585 | yesterday | Apache-2.0 | Mac, Windows, Linux |
| jundot / omlx | 23,475 | 4 days ago | Apache-2.0 | Mac |
More: download files, languages, topics and project record
Download files, v3.2.1
- Mac2 files, 9 downloads
- Windows1 file, 2 downloads
- Linux2 files, 5 downloads
Languages
- Rust 94%
- Python 3%
- Shell 2%
- PowerShell <1%
Topics
- apple-silicon
- llama-cpp
- llm
- local-llm
- mlx
- monitoring
- ollama
- rust
- tui
- vllm
Project record
- JobLocal LLMs
- StatusListed
- Commits182
- Forks15
- Watching0
- Stars in 28 days+53
- CreatedSep 11, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026