
PaddlePaddle / PaddleOCR
Turn any PDF or image document into structured data for your AI. A powerful, lightweight OCR toolkit that bridges the gap between images/PDFs and LLMs. Supports 100+ languages.
Why this job: topics: rag, document-parsing, ocr
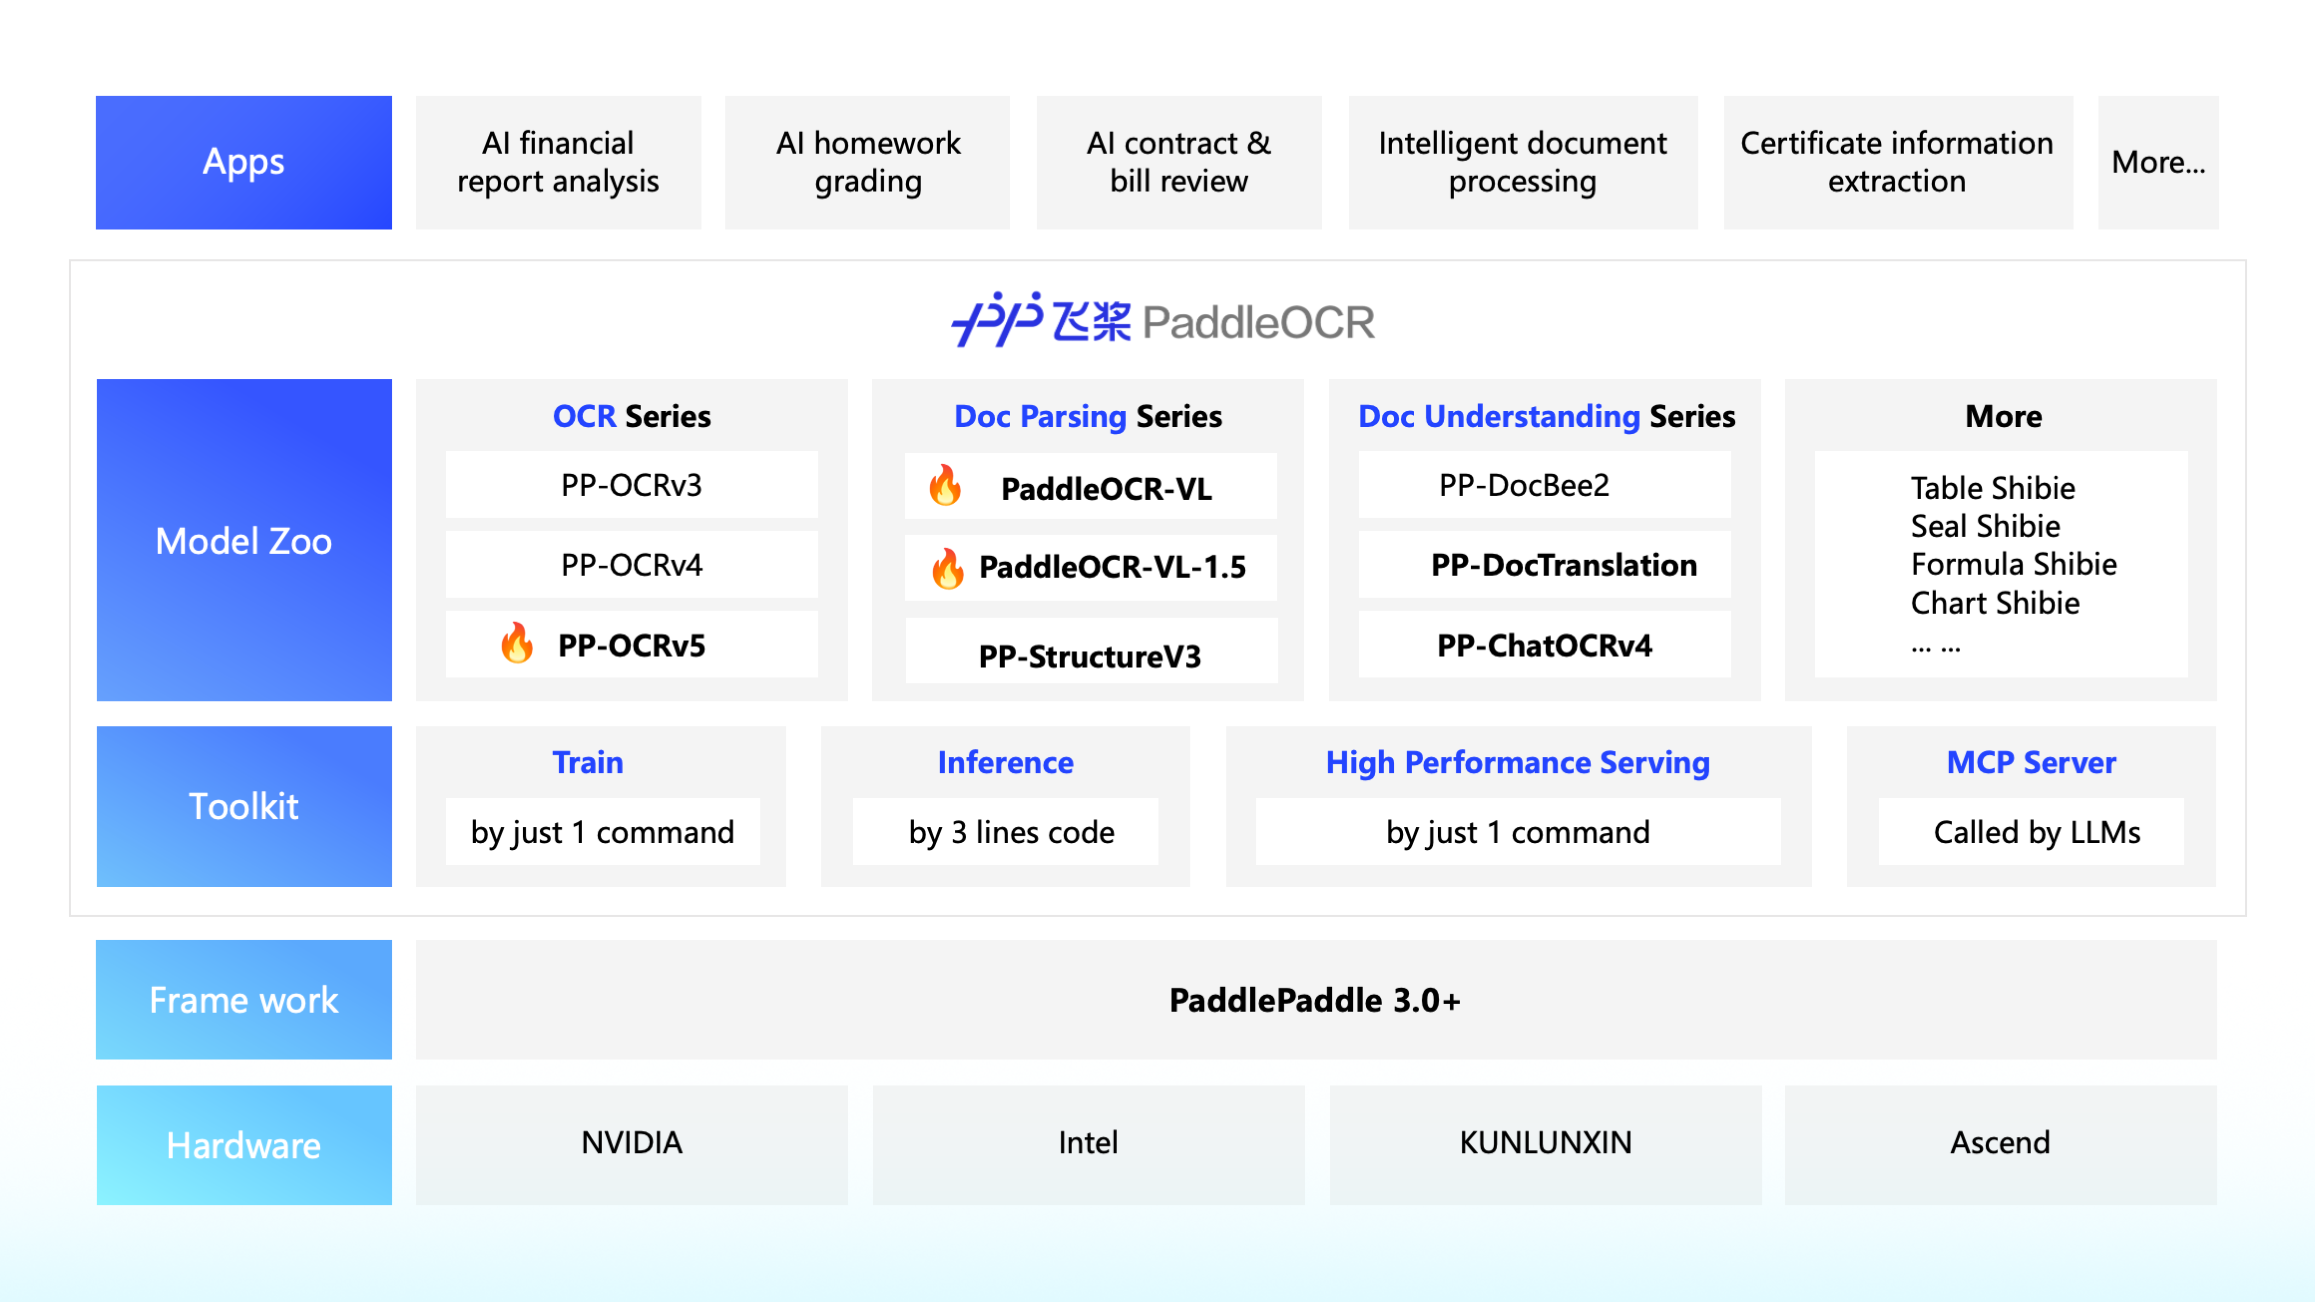
What it does
- SOTA Document VLM. Featuring PaddleOCR-VL-1.6 (0.9B), the industry's leading lightweight vision-language model for document parsing. It achieves 96.3% accuracy on OmniDocBench v1.6, leads in text, formula, and table recognition, and shows s
- Structure-Aware Conversion. Powered by PP-StructureV3, seamlessly convert complex PDFs and images into Markdown or JSON. Unlike the PaddleOCR-VL series models, it provides more fine-grained coordinate information, including table cell coord
- Production-Ready Efficiency. Achieve commercial-grade accuracy with an ultra-small footprint. Outperforms numerous closed-source solutions in public benchmarks while remaining resource-efficient for edge/cloud deployment.
- 100+ Languages Supported. Native recognition for a vast global library. PP-OCRv6 supports 50 languages with a single unified model (Chinese, English, Japanese, and 46 Latin-script languages) — no model switching needed for multilingual docu
- Complex Element Mastery. Beyond standard text recognition, we support natural scene text spotting across a wide range of environments, including IDs, street views, books, and industrial components
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 54 days ago
- Stars
- 92,460
- +315 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v3.7.0
- Released 5 months ago
- Built with
- Python
- 68% of the code
Is it looked after?
- Contributors
- 1
- Last 90 days
- Issues
- 98% closed
- 170 still open
- Pull requests
- 3,201 merged
- 91 waiting
- Releases
- 33
- 7 in the last year
- No contributing guide
- No security policy
- No code of conduct
More: languages, topics and project record
Languages
- Python 68%
- C++ 11%
- TypeScript 6%
- Shell 5%
Topics
- ocr
- chineseocr
- pdf2markdown
- pp-ocr
- pp-structure
- document-parsing
- document-translation
- kie
- ai4science
- pdf-extractor-rag
- pdf-parser
- rag
Project record
- JobRAG and search
- StatusListed
- Commits6,927
- Forks11,636
- Watching567
- Stars in 28 days+1,604
- CreatedMay 8, 2020
- First seen by usNov 7, 2026
- CheckedNov 9, 2026