
paulpierre / markdown-crawler
A multithreaded 🕸️ web crawler that recursively crawls a website and creates a 🔽 markdown file for each page, designed for LLM RAG
Why this job: says: web crawler
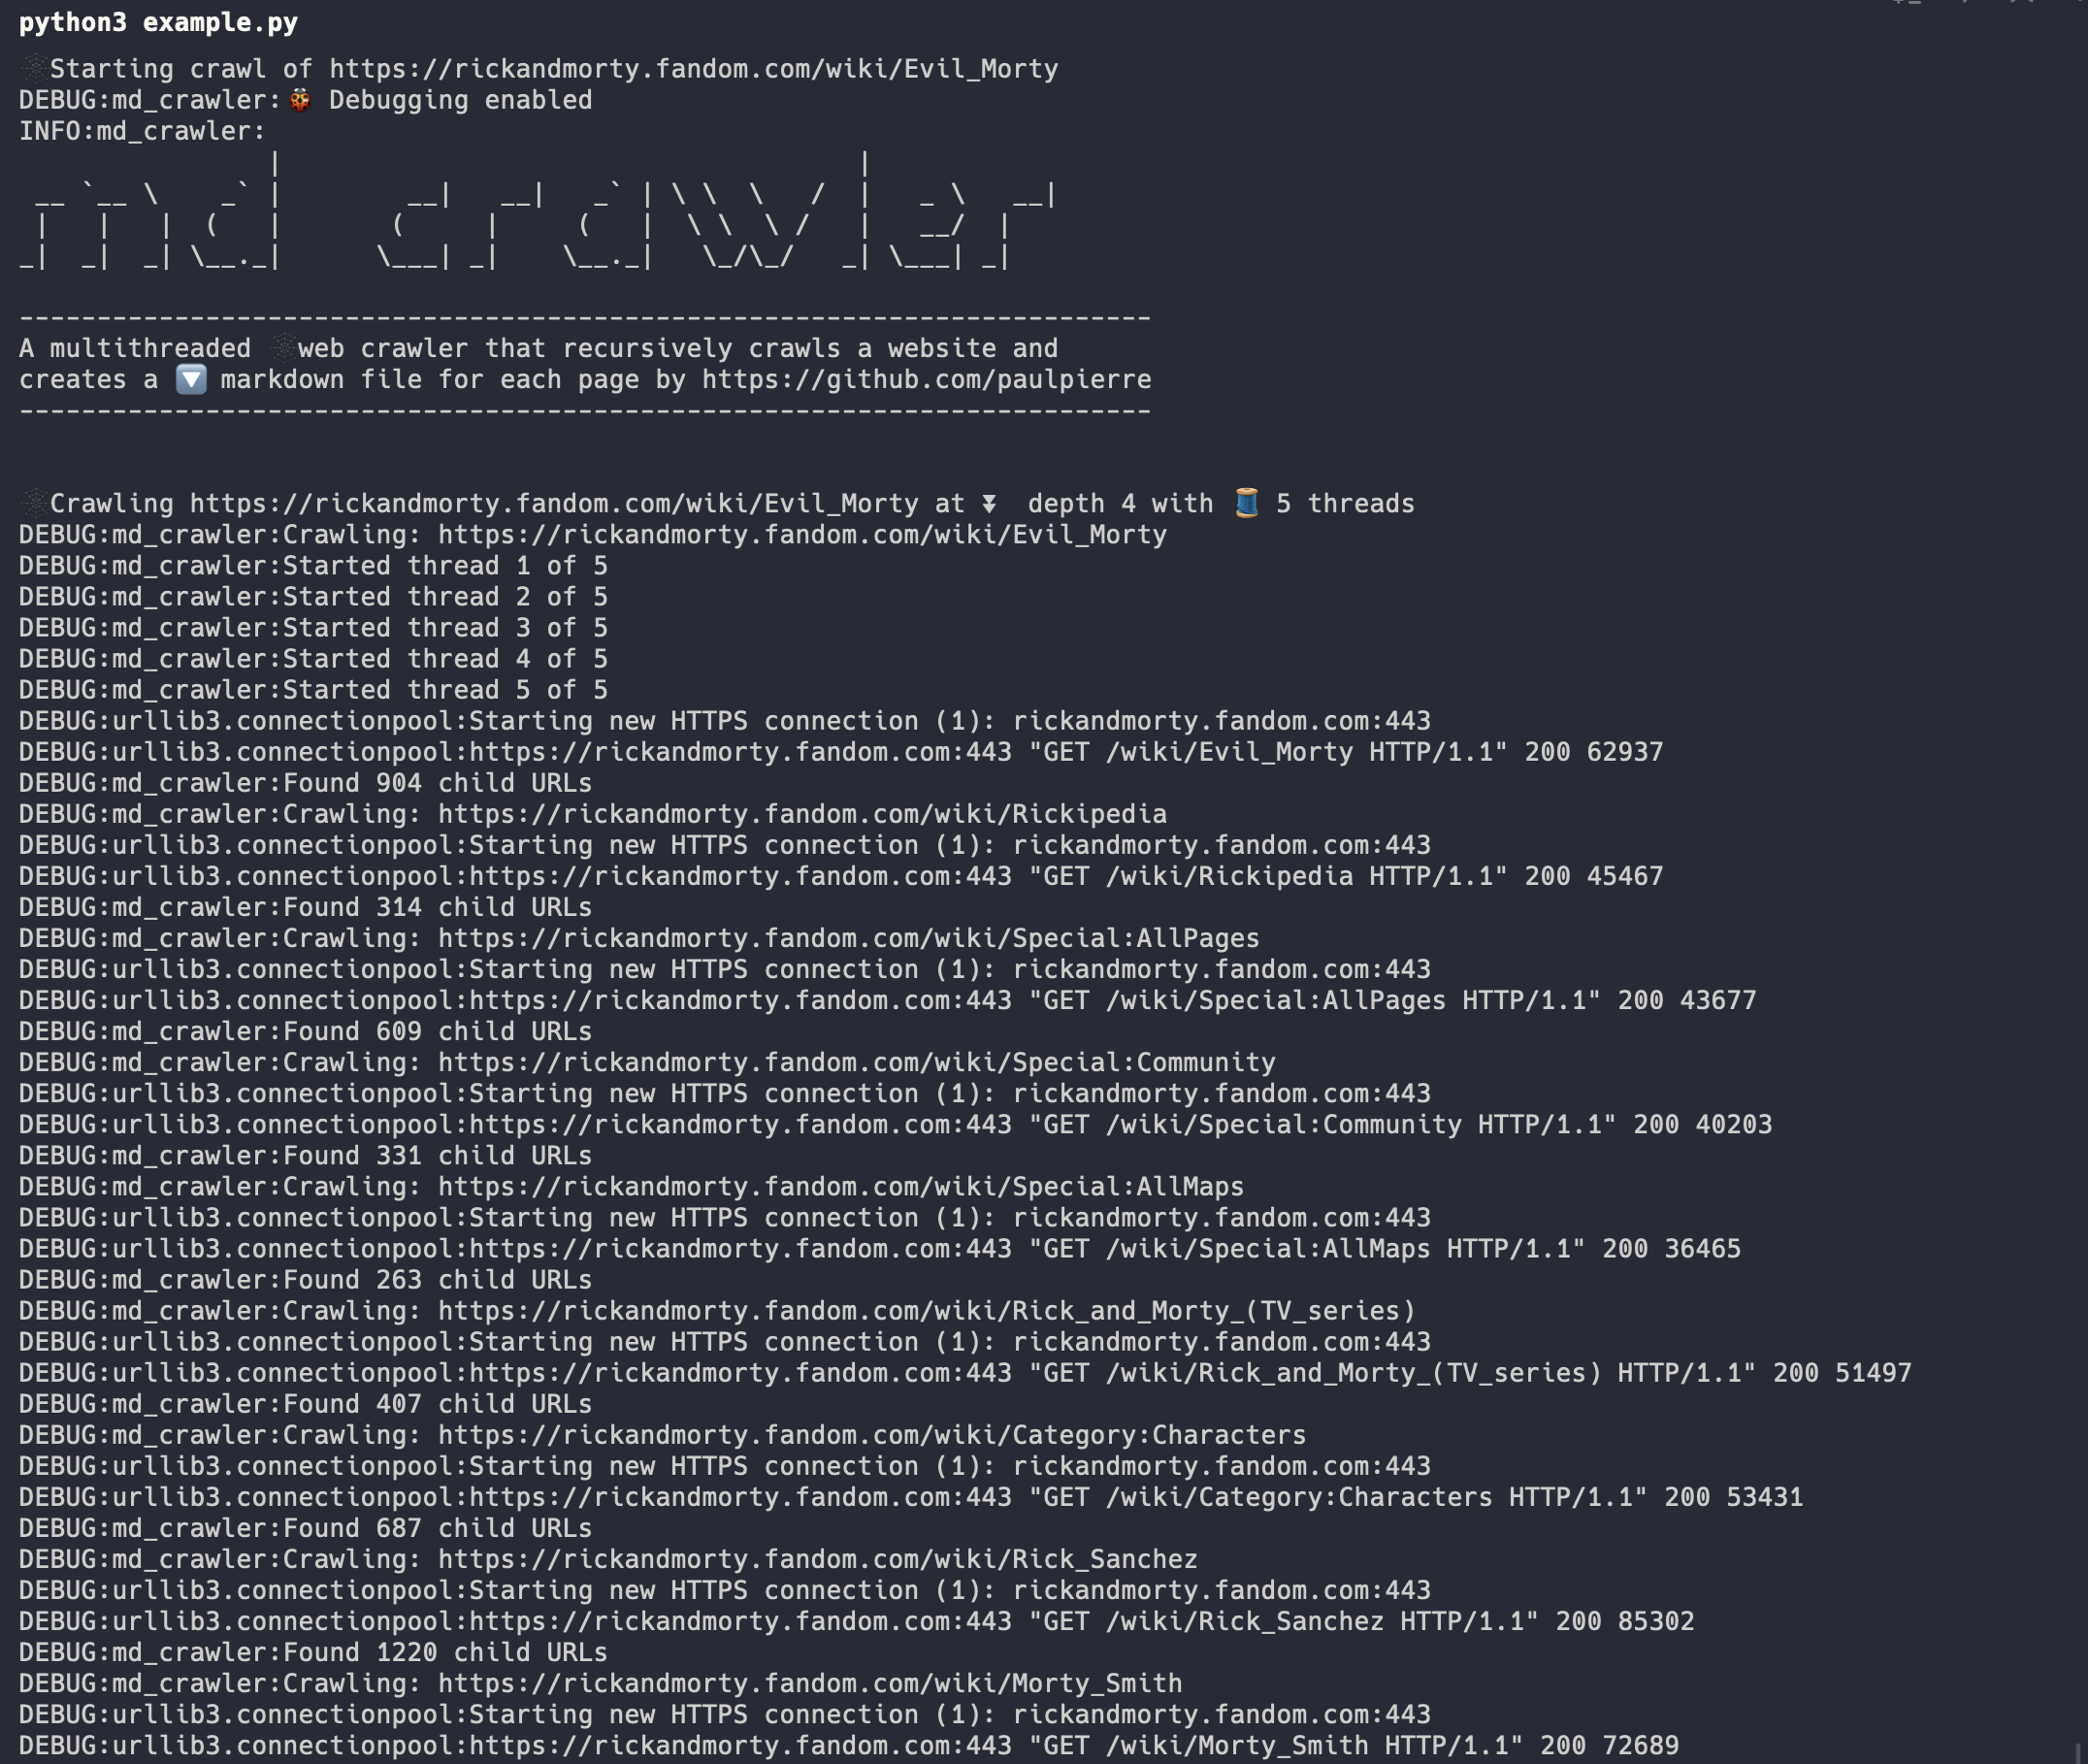
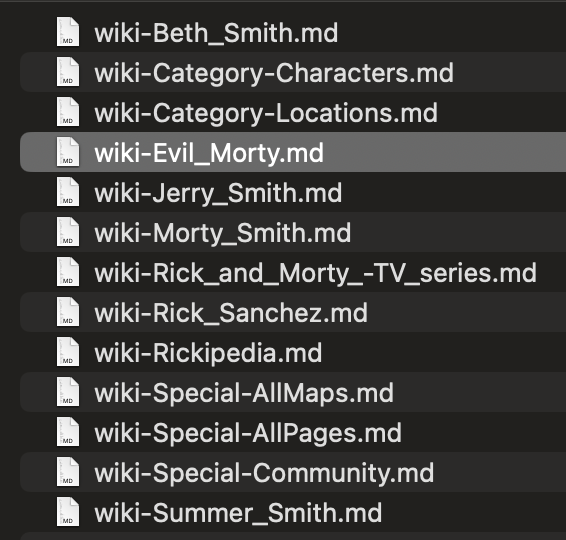
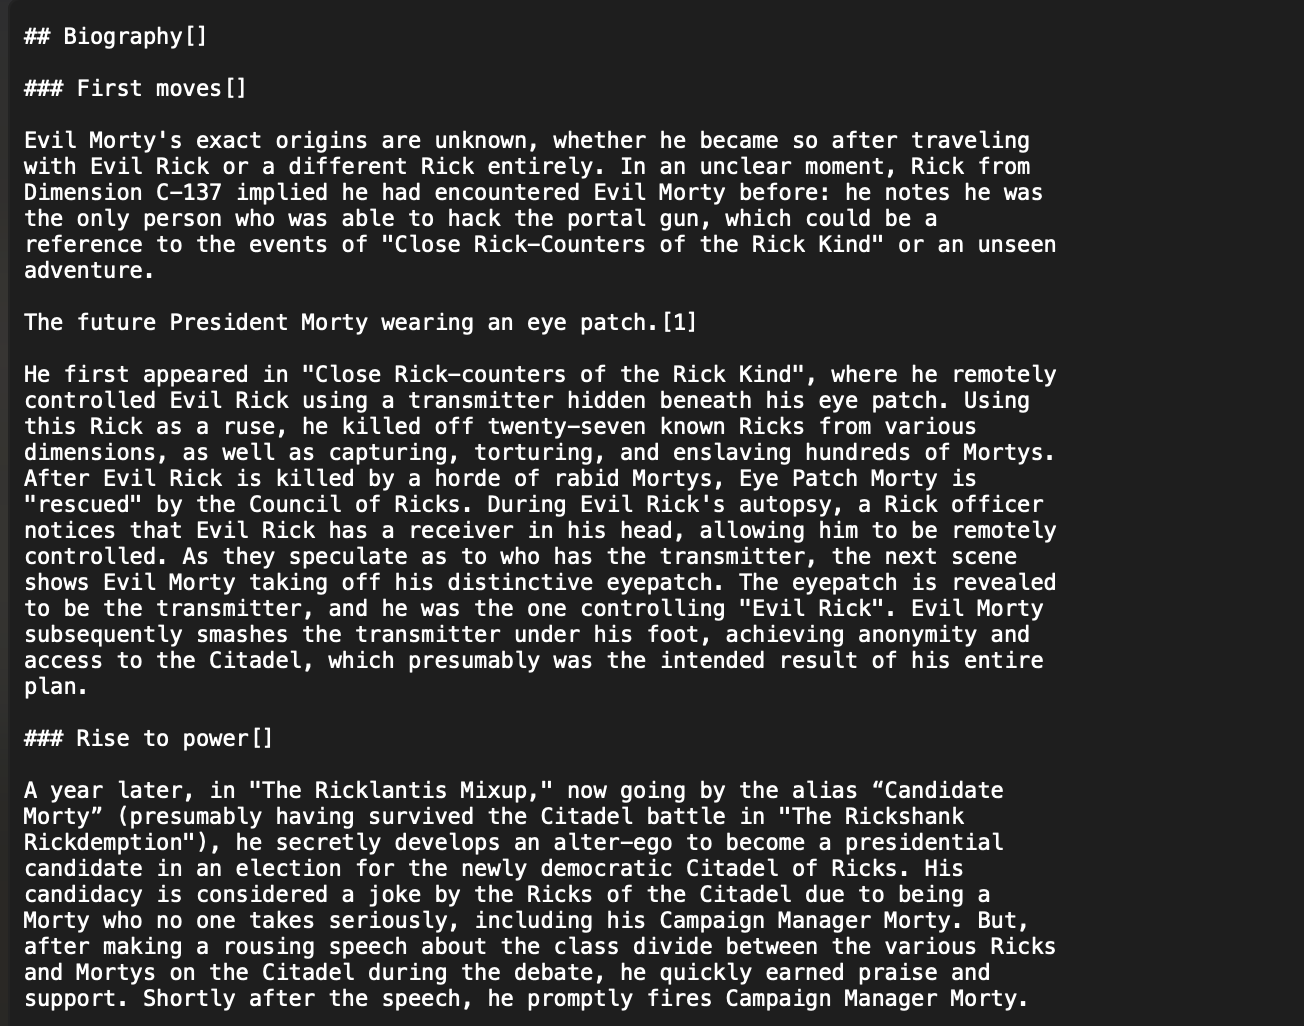
What it does
This is a multithreaded web crawler that crawls a website and creates markdown files for each page. It was primarily created for large language model document parsing to simplify chunking and processing of large documents for RAG use cases. Markdown by nature is human readable and maintains document structure while keeping a small footprint.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 4 months ago
- Stars
- 480
- +1 this week
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v0.0.9
- Released 4 months ago
- Built with
- Python
- 100% of the code
Is it looked after?
- Contributors
- 0
- Last 90 days
- Issues
- 55% closed
- 5 still open
- Pull requests
- 1 merged
- 0 waiting
- Releases
- 3
- 1 in the last year
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| firecrawl / firecrawl | 200,182 | today | AGPL-3.0 | No downloads |
| fastcrw / crw | 1,240 | yesterday | AGPL-3.0 | Mac, Linux |
More: languages, topics and project record
Languages
- Python 100%
Topics
- html-to-markdown
- html-to-markdown-converter
- html2md
- llm
- llmops
- markdown
- markdown-crawler
- markdown-parser
- markdown-scraper
- md-crawler
- rag
- web-scraper
Project record
- JobAutomation and scraping
- StatusListed
- Commits18
- Forks53
- Watching5
- Stars in 28 days+8
- CreatedOct 24, 2023
- First seen by usNov 7, 2026
- CheckedNov 7, 2026