
PhiloLabs / agentic-vbench
AgenticVBench: Can AI Agents Complete Real-World Post-Production Tasks?
Why this job: topics: llm-evaluation, benchmark
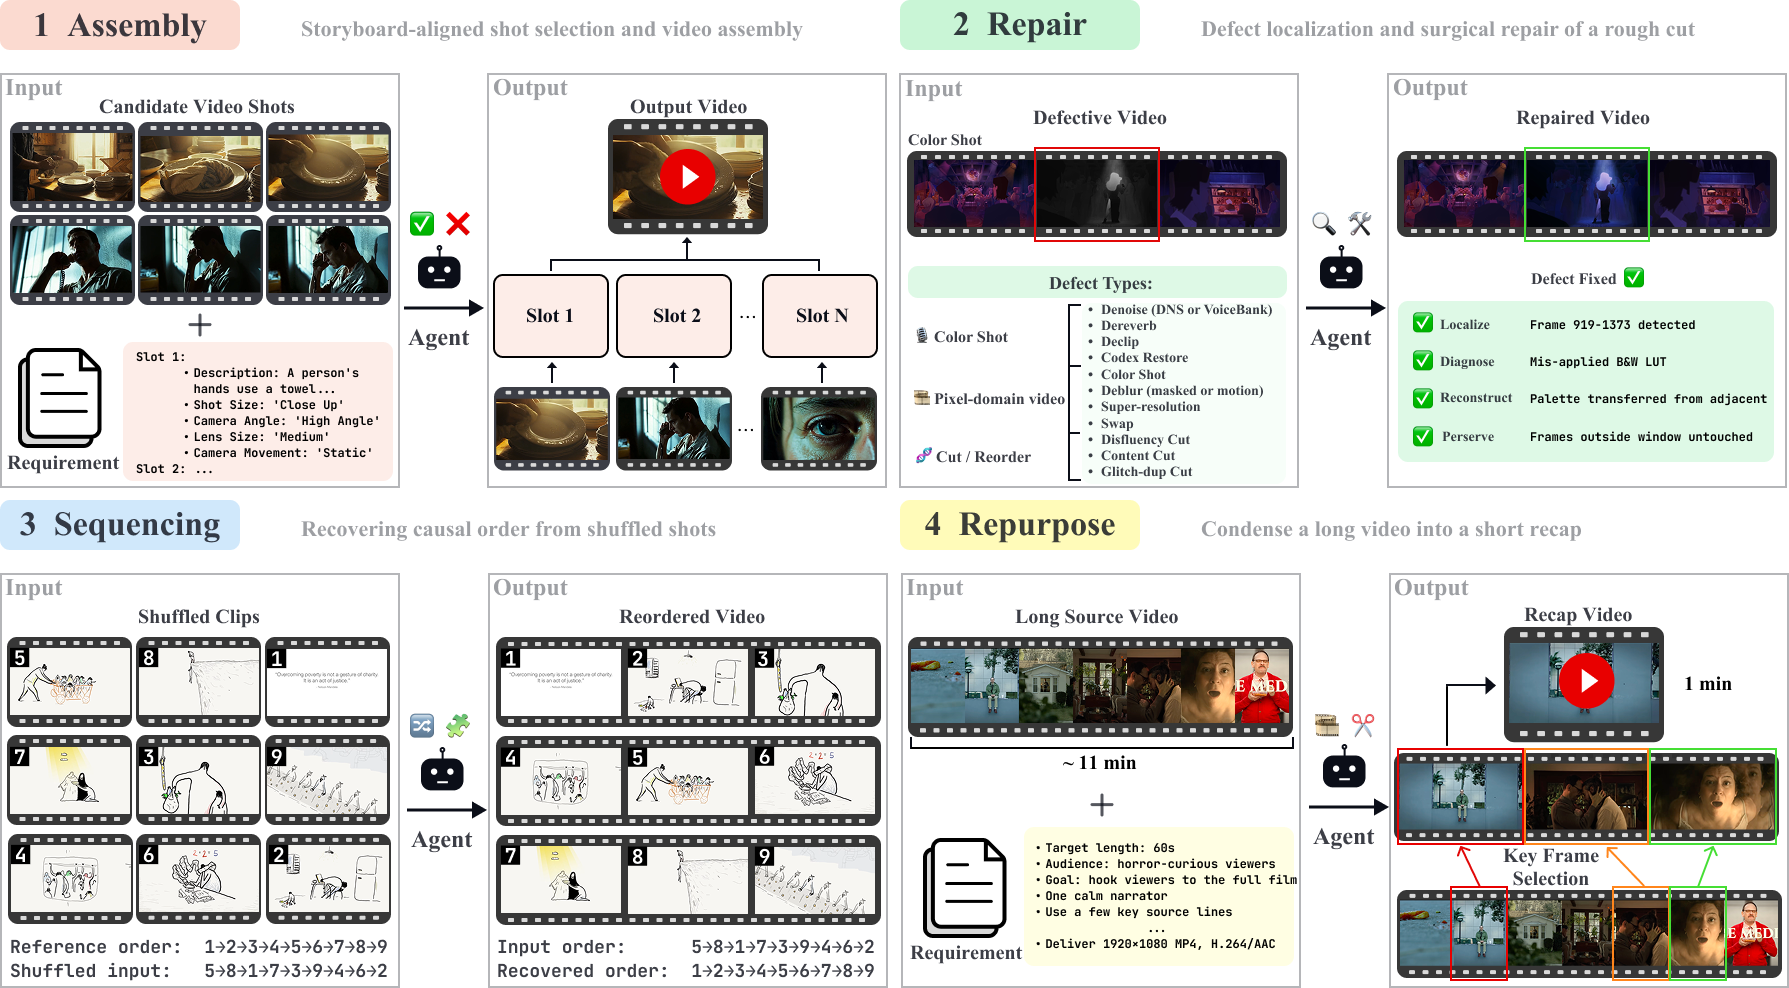
What it does
Built on Harbor — agent installation, sandboxed execution, concurrency, and trial scoring are handled for you.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 32 days ago
- Stars
- 112
- On GitHub
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest tag
- media-v1
- Released 5 months ago
- Built with
- Python
- 82% of the code
Is it looked after?
- Contributors
- 8
- Last 90 days
- Issues
- 36% closed
- 29 still open
- Pull requests
- 65 merged
- 11 waiting
- Releases
- 1
- 1 in the last year
- Contributing guide (opens in new tab)
- No security policy
- Code of conduct (opens in new tab)
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| mll-lab-nu / embodied-first-exam | 242 | today | MIT | No downloads |
| sierra-research / tau2-bench | 2,424 | 6 days ago | MIT | No downloads |
| keli-wen / agy-staff | 835 | 3 days ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 82%
- Shell 14%
- Dockerfile 3%
- JavaScript 1%
Topics
- ai-agents
- benchmark
- harbor
- llm-evaluation
- video-editing
Project record
- JobEvals and observability
- StatusListed
- Commits289
- Forks30
- Watching0
- Stars in 28 days+6
- CreatedMay 11, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026