
rodricios / wxpath
wxpath - declarative web crawling with XPath; a Web Query Language (WQL)
Why this job: topics: crawler, scraper
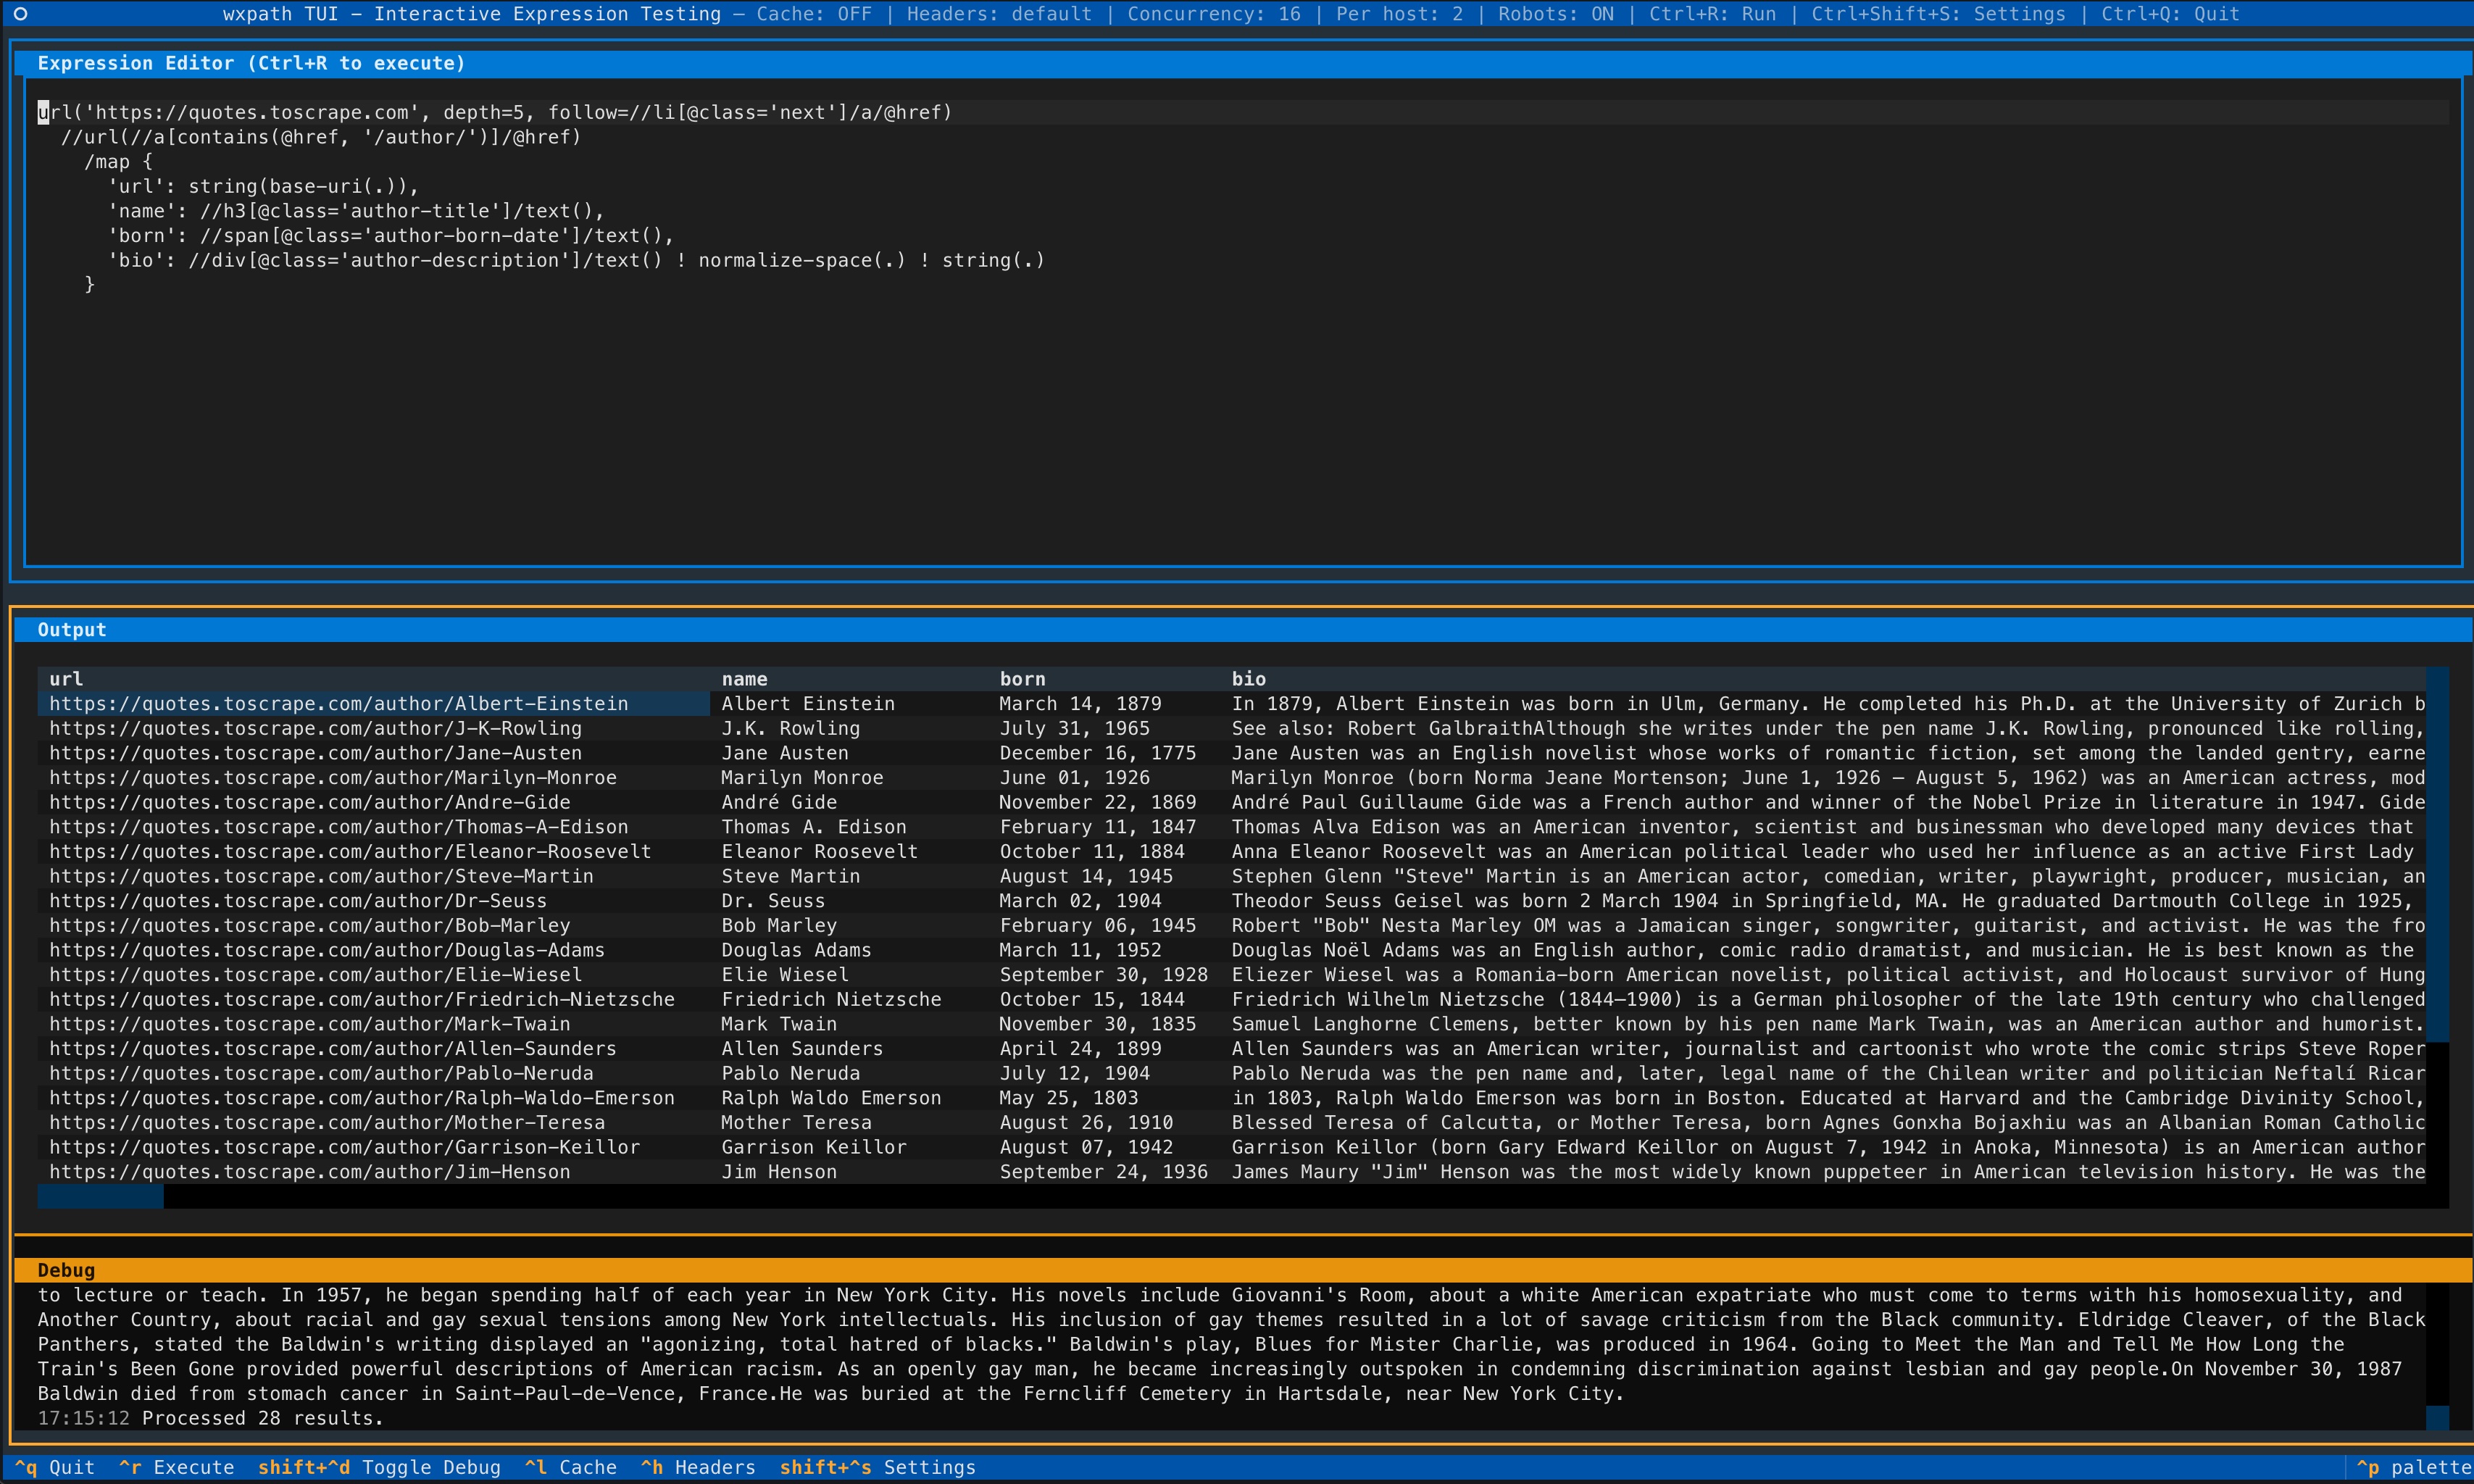
What it does
This expression fetches a page, extracts links, and streams them concurrently - no crawl loop required:
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 4 months ago
- Stars
- 110
- On GitHub
- Licence
- AGPL-3.0
- Share-alike, even hosted
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 100% of the code
Is it looked after?
- Contributors
- 0
- Last 90 days
- Issues
- None
- No issues filed
- Pull requests
- 25 merged
- 2 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| unclecode / crawl4ai | 87,156 | 6 days ago | Apache-2.0 | No downloads |
| firecrawl / firecrawl | 200,182 | today | AGPL-3.0 | No downloads |
| alirezamika / autoscraper | 8,080 | 3 months ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 100%
Topics
- crawler
- data-extraction
- data-loader
- data-mining
- extract-data
- rag
- scraper
- web-graph-traversal
- web-query-language
Project record
- JobAutomation and scraping
- StatusListed
- Commits35
- Forks5
- Watching2
- Stars in 28 days0
- CreatedJul 24, 2025
- First seen by usNov 7, 2026
- CheckedNov 7, 2026