
vakra-dev / reader
Open source web infrastructure for AI. Scrape, crawl, and automate the web, clean markdown, browser sessions, ready for your agents.
Why this job: topics: web-scraping, crawler, scraper, web-crawler
What it does
- Browser Sessions. Launch stealthed Chrome, connect Playwright/Puppeteer via CDP
- Anti-Bot Bypass. TLS fingerprinting, navigator spoofing, WebRTC masking, webdriver=false
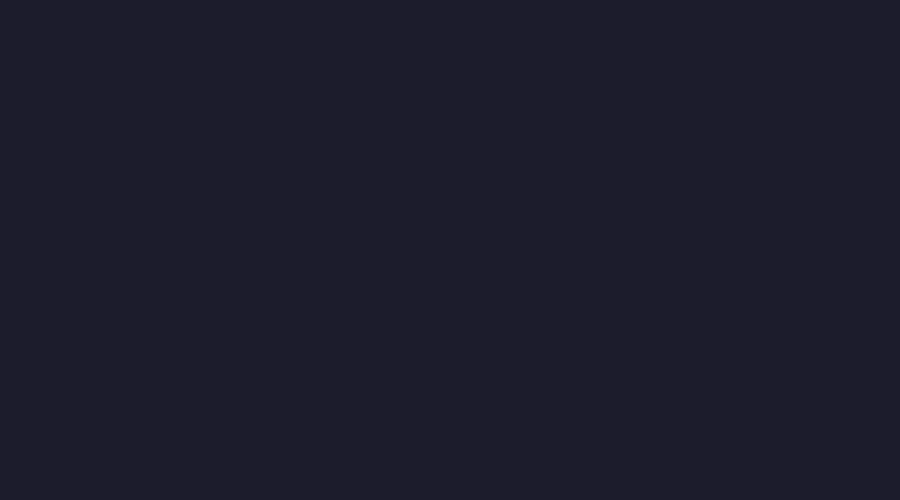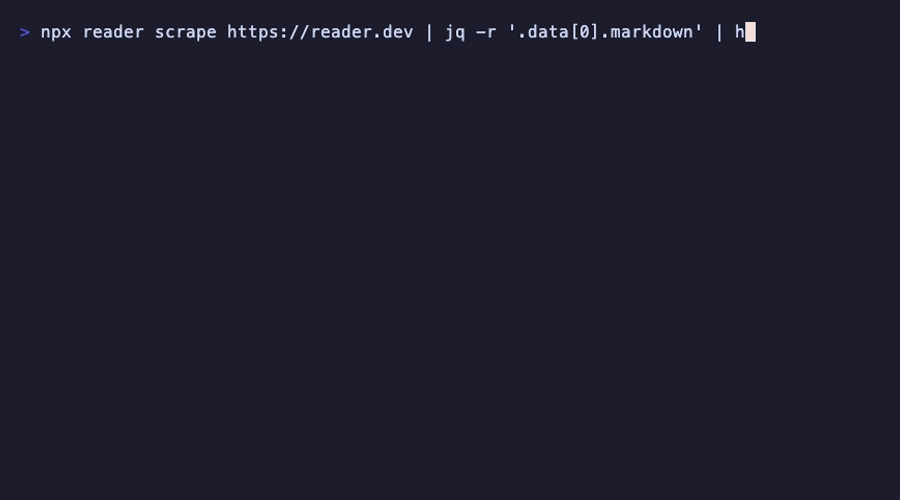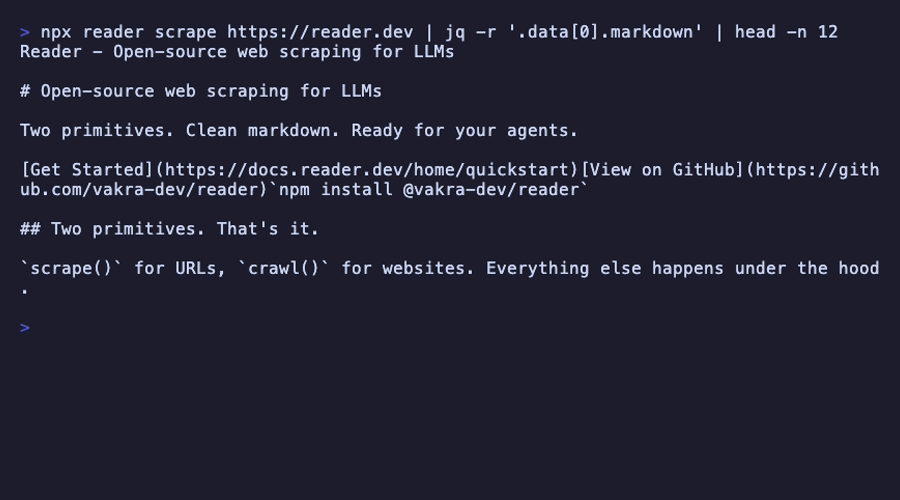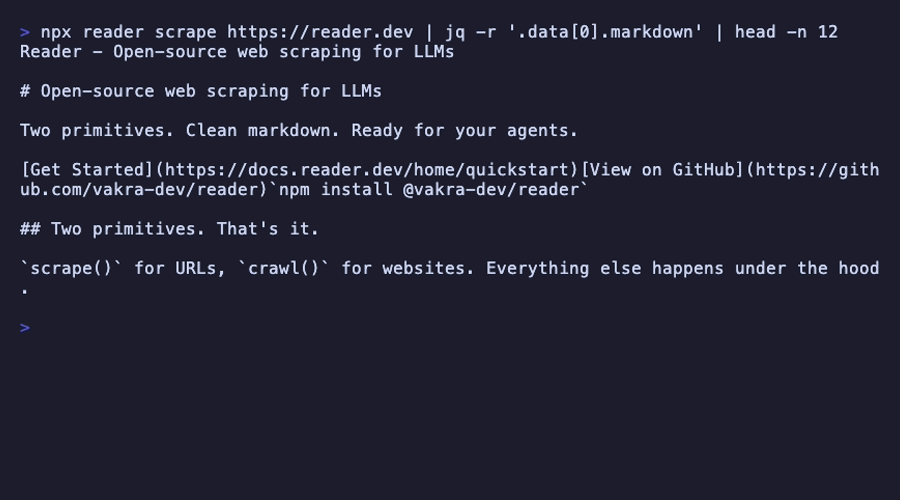
- Clean Output. Markdown and HTML with automatic main content extraction
- Smart Content Cleaning. Removes nav, headers, footers, popups, cookie banners
- CLI & API. Use from command line or programmatically
Get started
npm install @vakra-dev/reader - Maintenance
- Active
- Last commit 34 days ago
- Stars
- 562
- +1 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v0.3.2
- Released 4 months ago
- Built with
- TypeScript
- 99% of the code
Is it looked after?
- Contributors
- 1
- Last 90 days
- Issues
- 100% closed
- 0 still open
- Pull requests
- 0 merged
- 0 waiting
- Releases
- 5
- 5 in the last year
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| firecrawl / firecrawl | 199,902 | today | AGPL-3.0 | No downloads |
| ScrapeGraphAI / Scrapegraph-ai | 32,645 | 34 days ago | MIT | No downloads |
| unclecode / crawl4ai | 87,122 | 5 days ago | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- TypeScript 99%
- Shell 1%
Topics
- ai
- ai-agents
- ai-crawler
- ai-scraper
- anti-bot
- crawler
- data-extraction
- firecrawl-alternative
- headless-browser
- html-to-markdown
- llm
- markdown
Project record
- JobAutomation and scraping
- StatusListed
- Commits49
- Forks41
- Watching0
- Stars in 28 days+5
- CreatedJan 7, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026